PyTorch has moved all media decoding and encoding into TorchCodec, leaving TorchVision and TorchAudio to focus on transforms. The libraries are now ABI stable, decoupling their release cadence from PyTorch's.
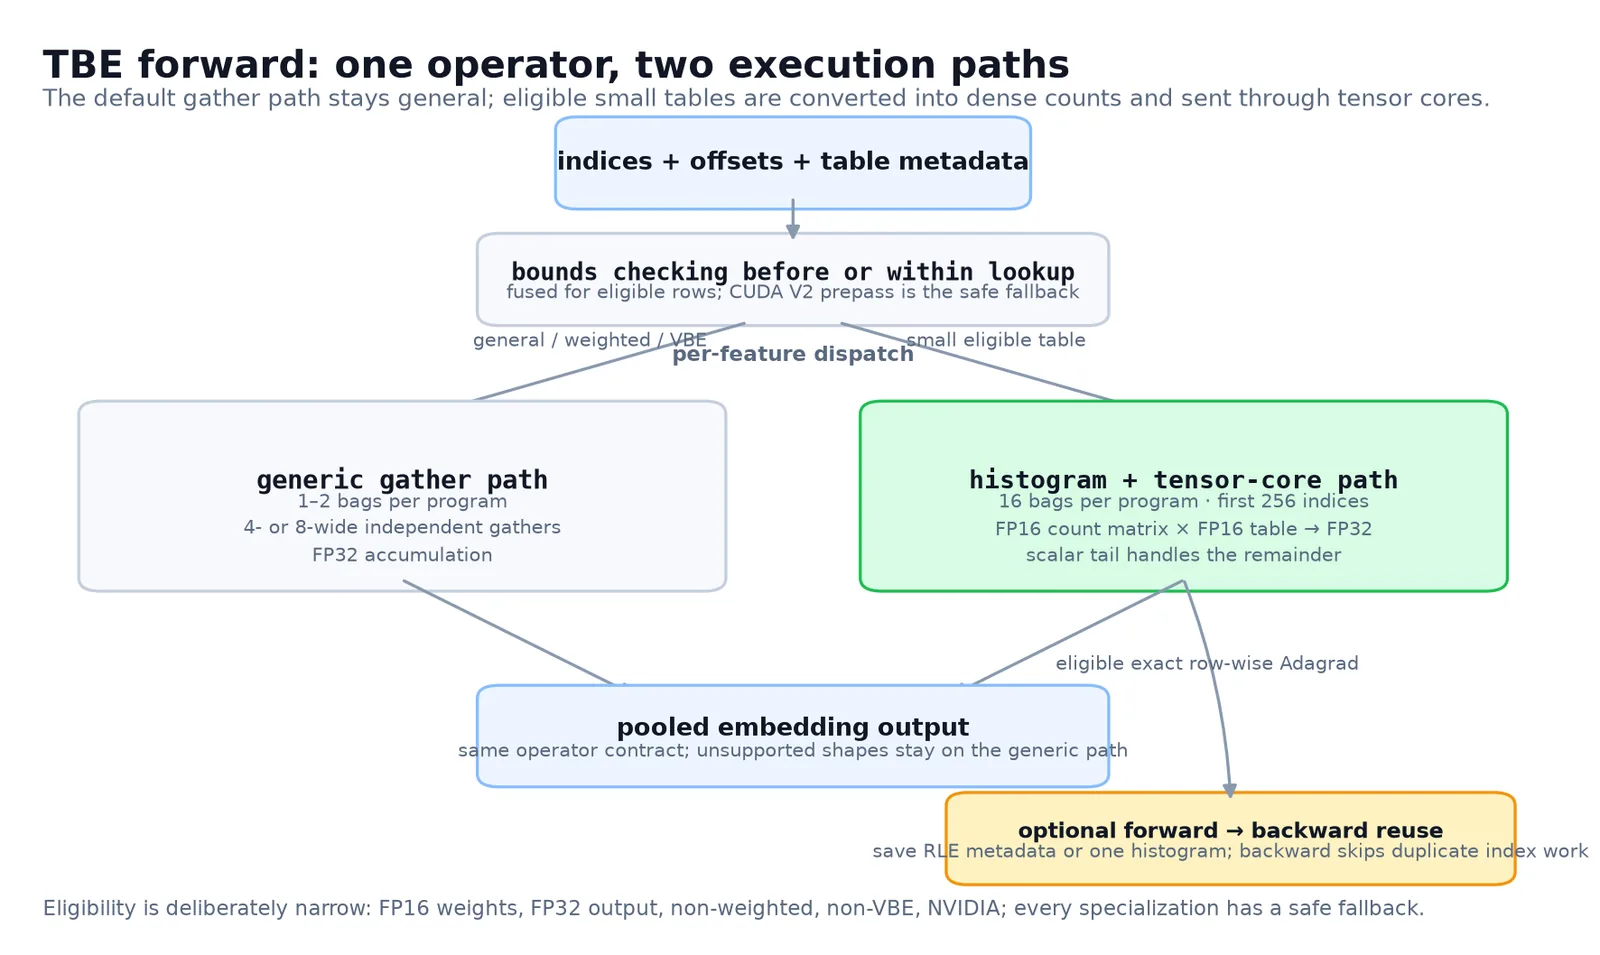
PyTorch's FBTriton reimplements table batched embedding kernels in Triton, achieving a median 1.28x forward speedup over legacy CUDA on GB200. The design uses config-driven optimizations, split runs, and Blackwell-specific features like CLC and TMA.
PyTorch and NVIDIA Dynamo introduce session-level identifiers for agentic workloads, enabling session-aware routing, admission control, and KV cache reuse across multi-turn reasoning chains.
AMD's TraceLens Agent turns raw PyTorch profiles into prioritized, evidence-backed optimization reports, using sub-agents for compute, system, and fusion analysis with guardrails for reliability.
Alibaba Cloud and Cambricon became Platinum members and Ant Group Gold member of the PyTorch Foundation, announced at PyTorch Conference China 2026 in Shanghai. Keynotes from these firms and Huawei covered the open AI stack from chips to deployment.
The PyTorch Ecosystem Working Group welcomed 10 new projects, including RLinf, Miles, SMG, TokenSpeed, and FiftyOne, expanding coverage from reinforcement learning to model serving and multimodal data.
AMD and PyTorch engineers upstreamed FP8 training optimizations for AMD Instinct GPUs into TorchTitan and TorchAO, delivering throughput gains on dense and MoE models through kernel fusion and format correctness fixes.
Together AI's new benchmark tests LLMs on 87 real-world multi-GPU kernel problems. The best model solves 28 correctly, and only 22 beat the PyTorch baseline, showing frontier models still lag on fast kernel generation.
NVIDIA's recsys-examples adds an end-to-end HSTU generative recommender workflow using PyTorch AOTI compilation and FlexKV-backed KV caching, reporting up to 5.93x lower latency on an RTX PRO 6000 Blackwell GPU.
PyTorch and Meta detail FlashAttention-4 with MXFP8 support, reaching 2.85 PF/s forward and 2 PF/s backward on LLM shapes, plus a zero-gather jagged module for Ads training.
PyTorch's Helion DSL now compiles to TPU via Pallas, with an autotuner choosing pipelining strategies. On flash attention, Helion hits 838 TFLOPs on TPU v7 and beats eager and compiled baselines across kernels.
We count visits on the server, cookie-free. You can also let this browser tell us how long you read, how far you scroll and which links you follow. It stays with us.
 Together AI
 NVIDIA