NVIDIA's AVO agent architecture, using Claude Opus 5, scored 100.00 RHAE on the ARC-AGI-3 public set, completing all 183 levels with about 12% fewer actions than VISTA. The result highlights system design over model capability alone.
PyTorch has moved all media decoding and encoding into TorchCodec, leaving TorchVision and TorchAudio to focus on transforms. The libraries are now ABI stable, decoupling their release cadence from PyTorch's.
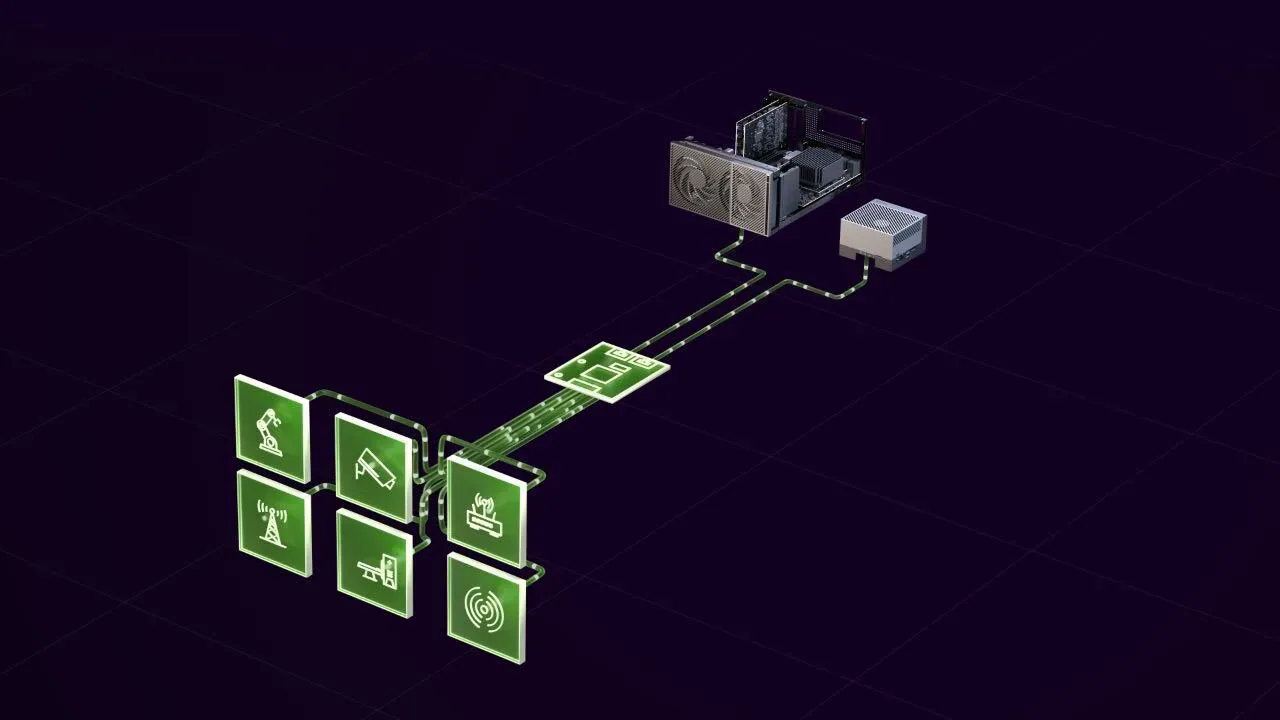
NVIDIA's State of AI in Telecommunications report finds 89% of operators say open source models matter to their AI strategy. The company also released a 30-billion-parameter Nemotron 3 Large Telco Model fine-tuned for telecom tasks.
AMD's new Typical Attained FLOPs (TAF) metric measures sustained GEMM throughput across a fixed set of workload-derived shapes. On one MI325X GPU, TAF results were 606 TFLOPs FP16, 616 TFLOPs BF16, and 1,143 TFLOPs unscaled FP8.
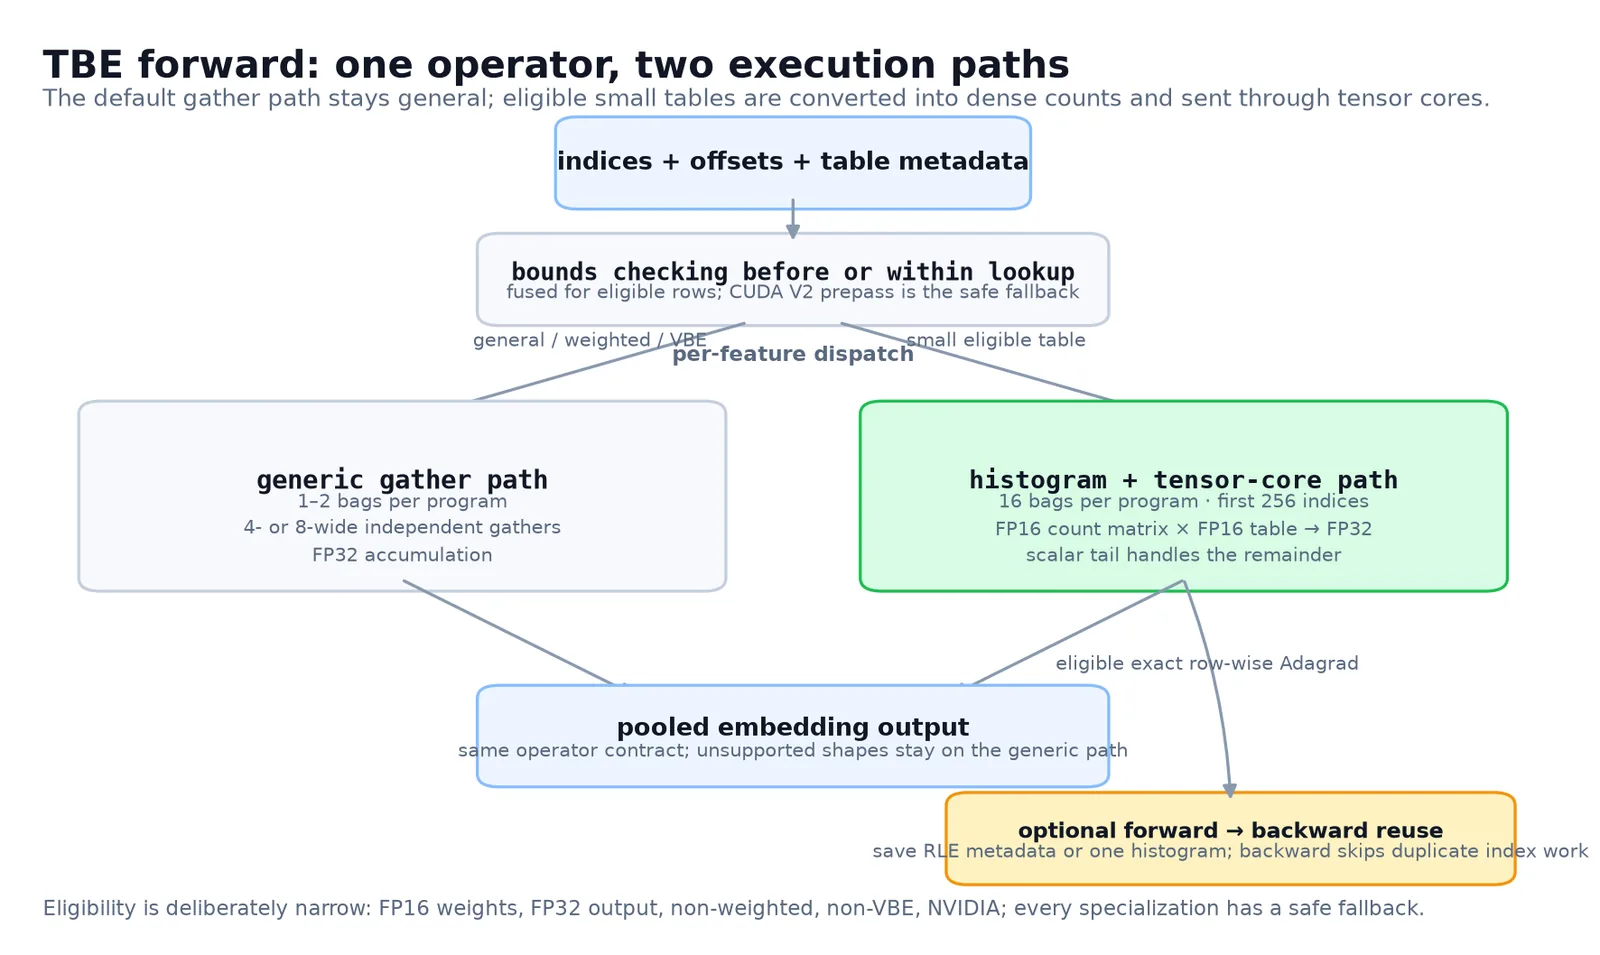
PyTorch's FBTriton reimplements table batched embedding kernels in Triton, achieving a median 1.28x forward speedup over legacy CUDA on GB200. The design uses config-driven optimizations, split runs, and Blackwell-specific features like CLC and TMA.
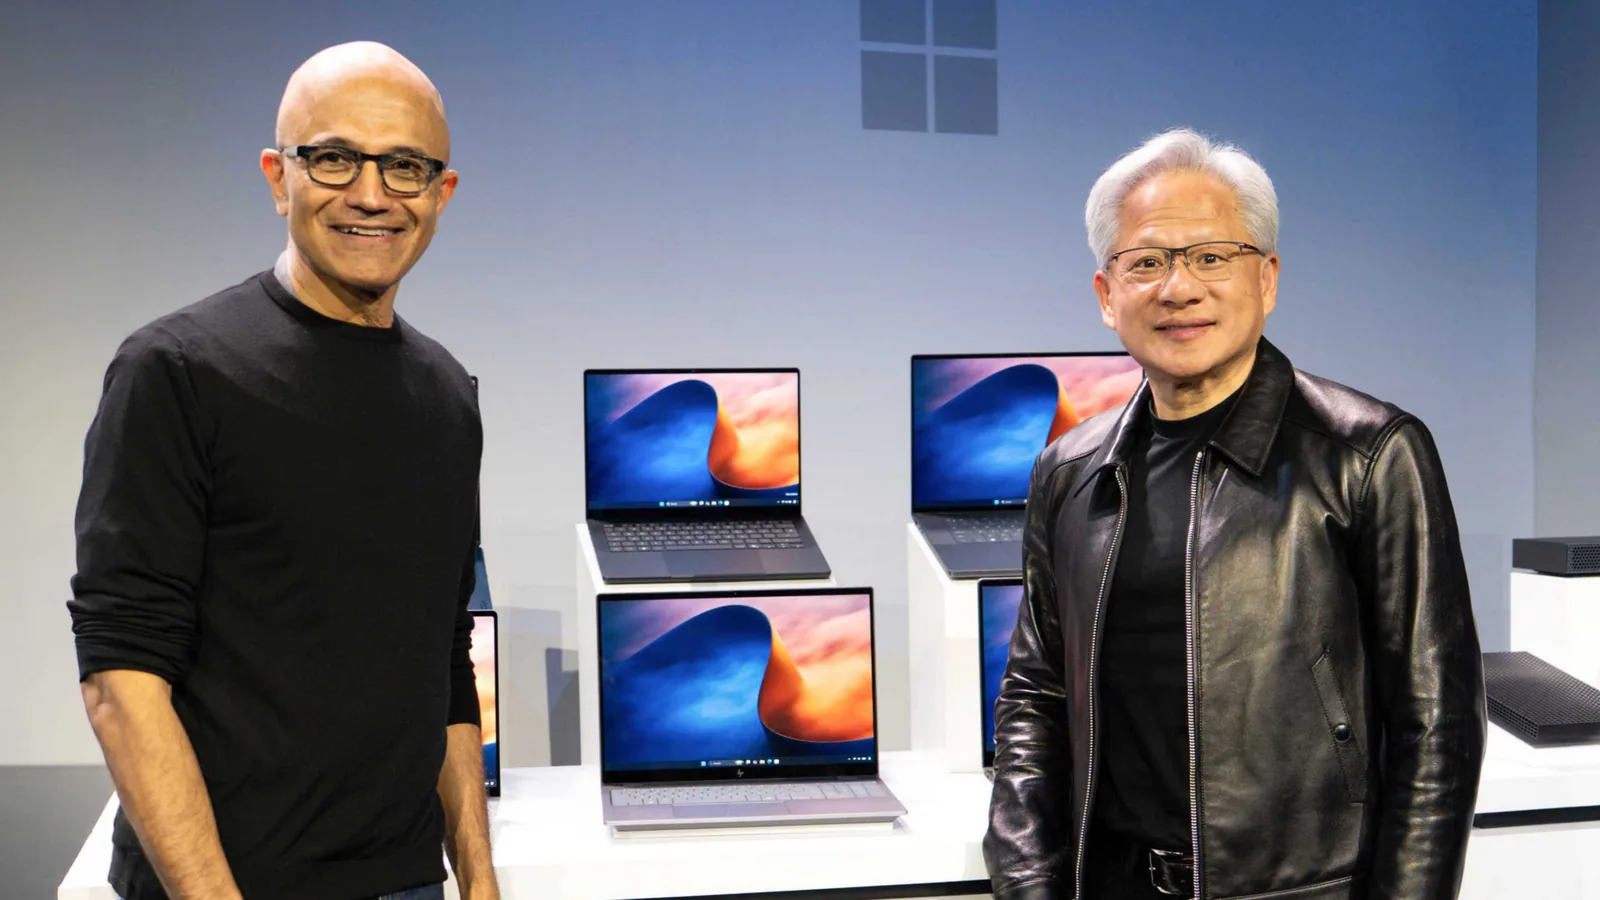
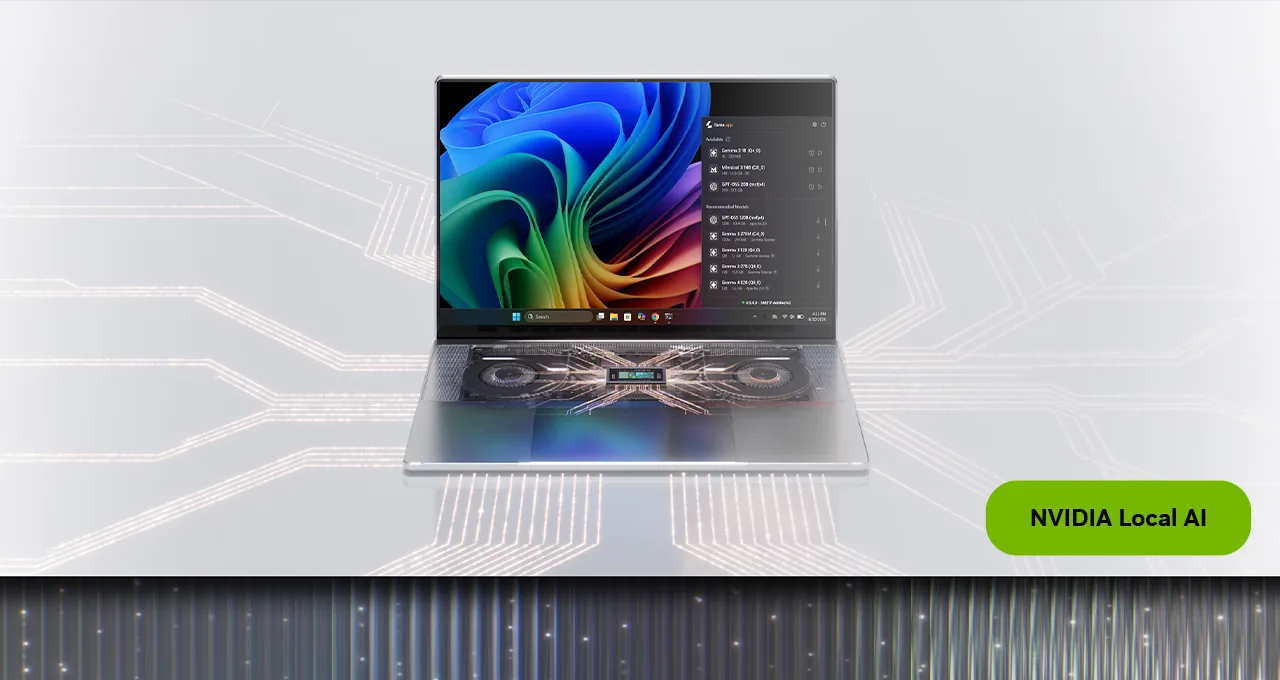
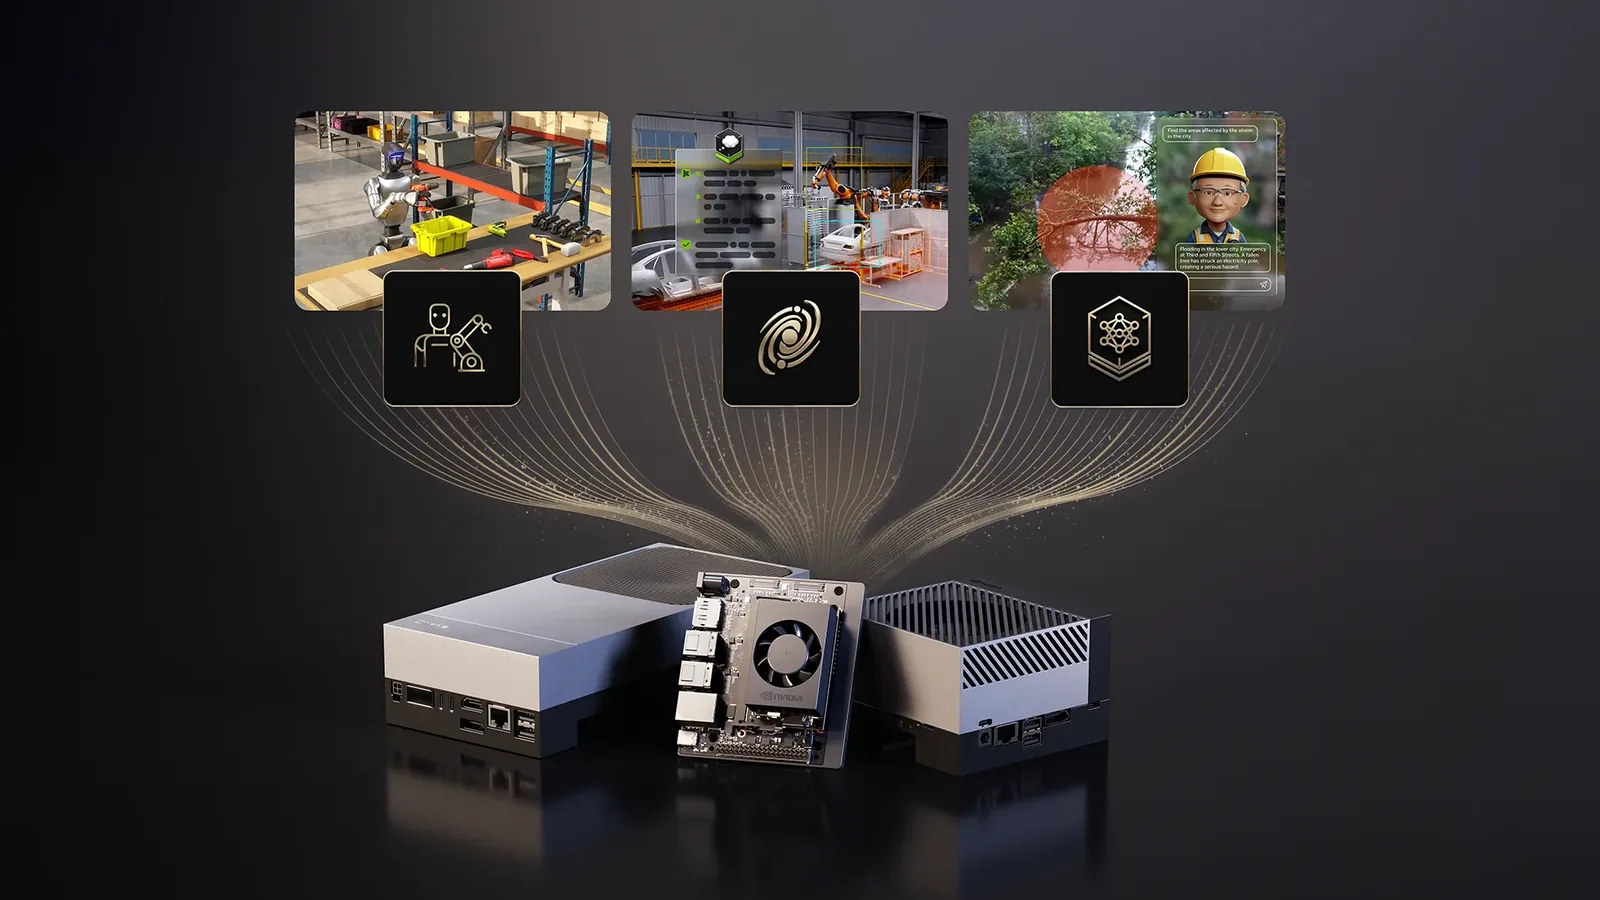
NVIDIA and Microsoft unveiled RTX Spark, a new Windows PC platform for local AI agents, with pre-orders starting October 7, 2026. The compact desktop and laptop variants offer up to 128 GB unified memory and one petaFLOP FP4 performance.
PyTorch and NVIDIA Dynamo introduce session-level identifiers for agentic workloads, enabling session-aware routing, admission control, and KV cache reuse across multi-turn reasoning chains.
AMD details serving Kimi-K3 MXFP4 on MI300X and MI325X using a 2P2D disaggregated setup, kernel substitution for MXFP4, and fixes for RDMA and recurrent-state bugs, achieving 57/57 recall at 900K tokens.
AMD published MI455X versus MI355X inference results from Advancing AI 2026, covering DeepSeek-V4-Flash serving ratios and microbenchmarks for MXFP4 GEMM, MLA decode bandwidth, and networking.
AMD's Primus framework pre-trains hybrid LLMs from scratch on eight MI355X GPUs, using a single configuration string to interleave MLA attention with linear-recurrent mixers. Five models completed training with no NaN values, and released configs allow reproduction.
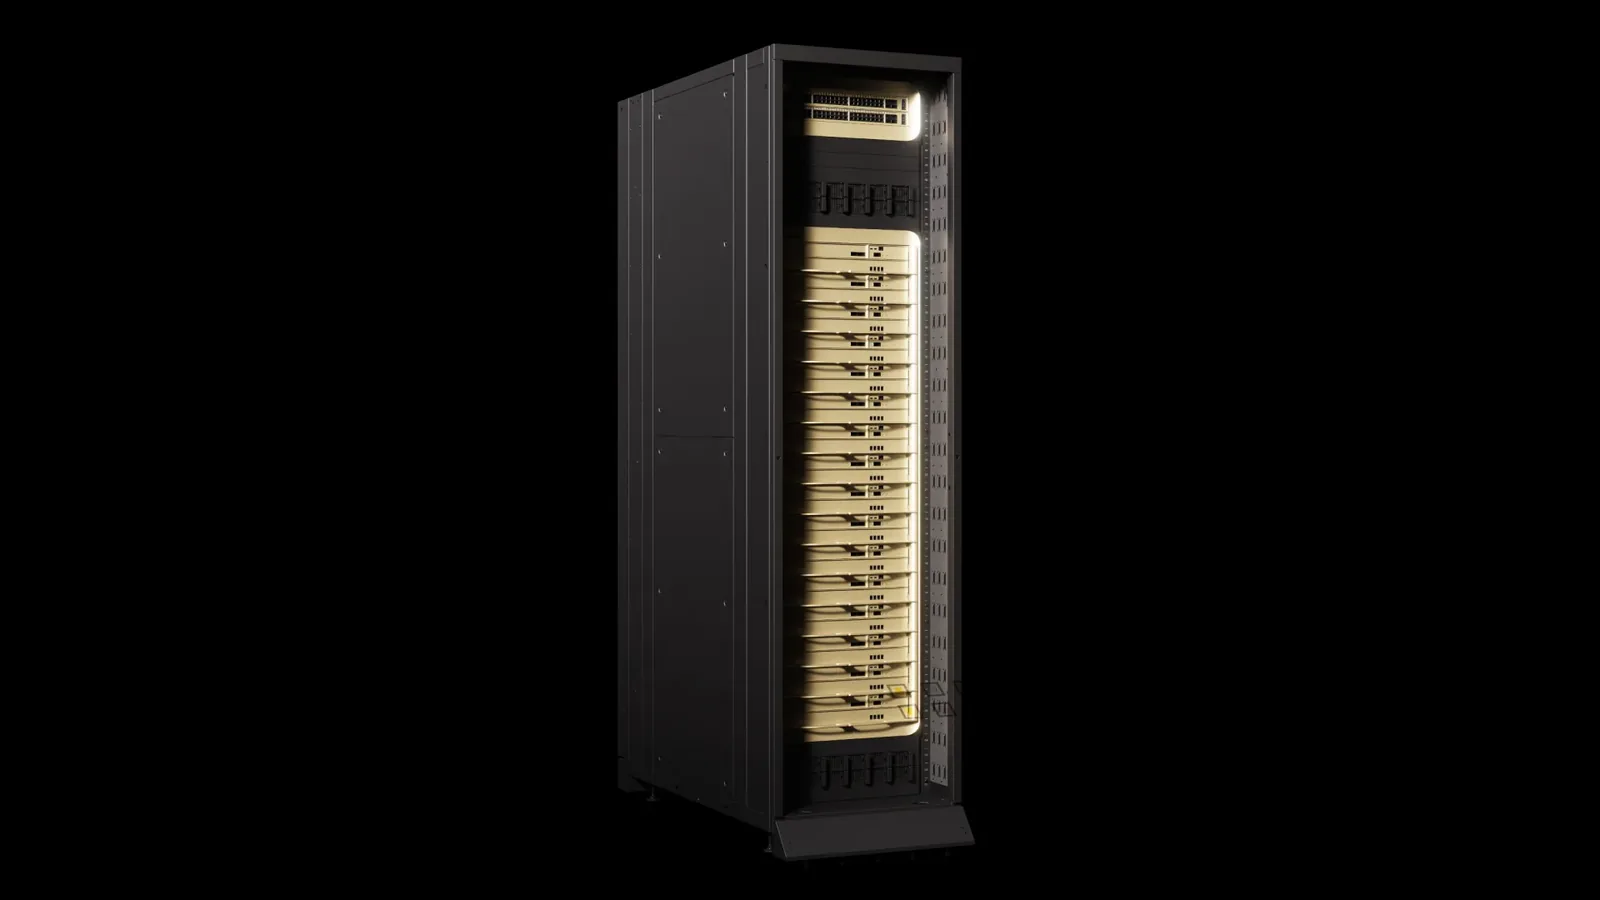
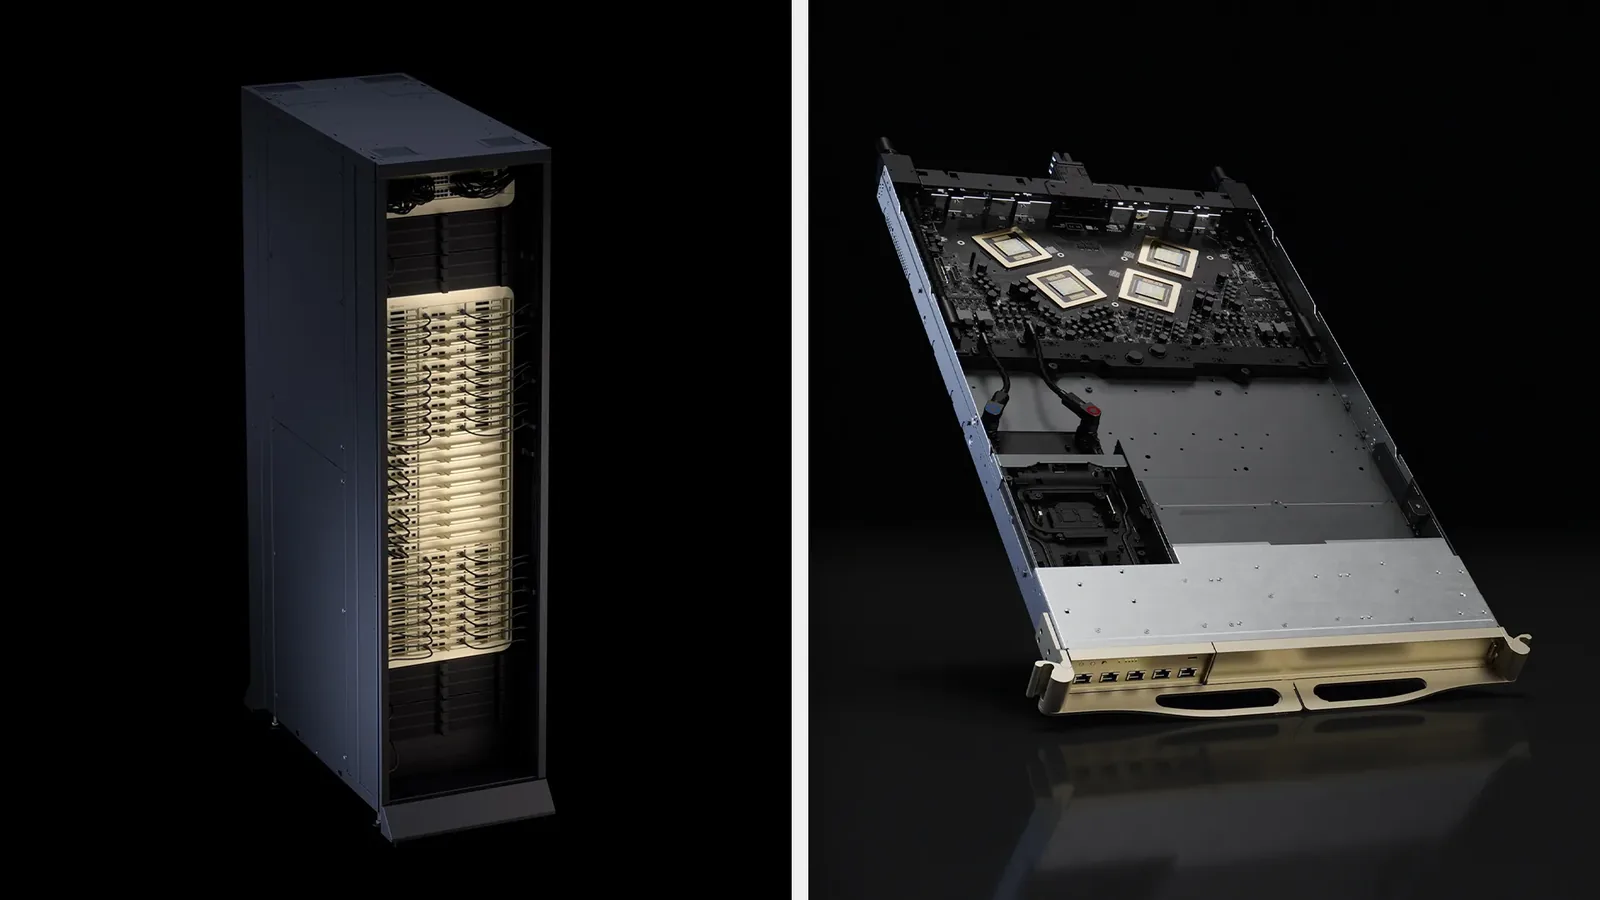
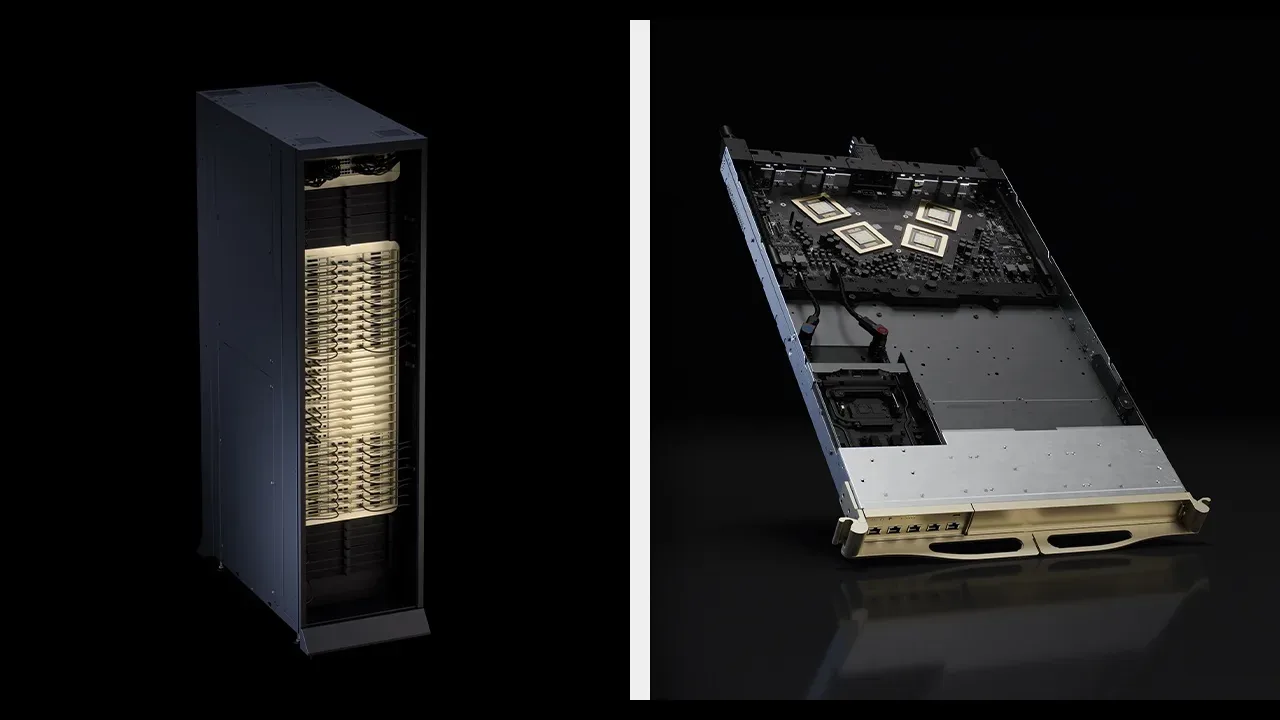
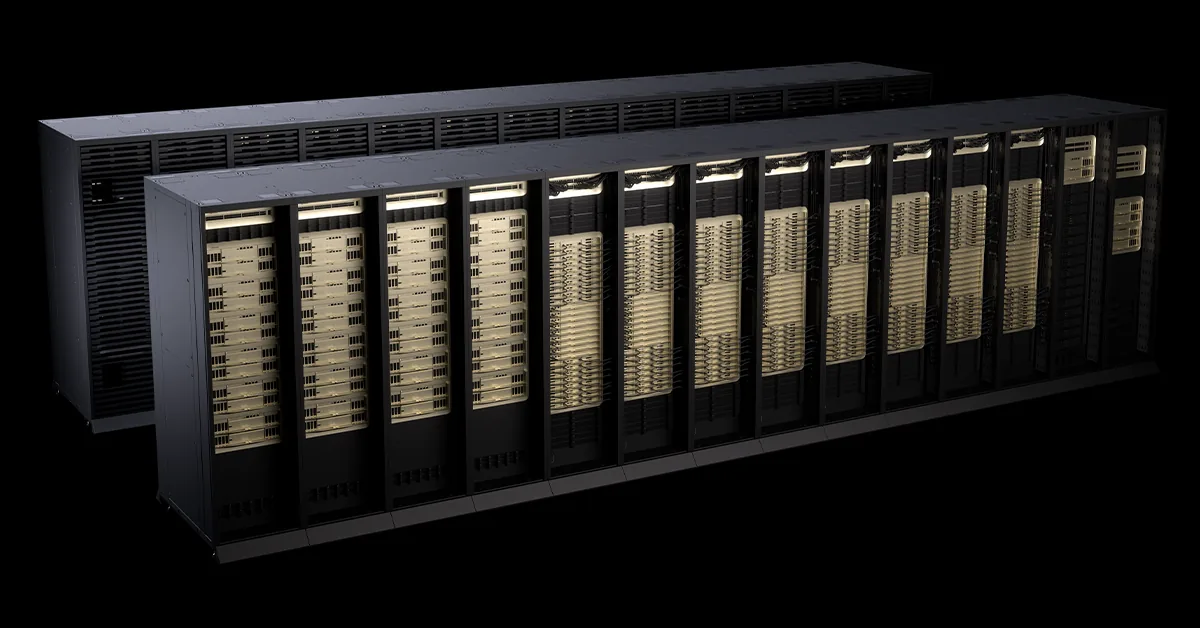
NVIDIA contributed Vera Rubin rack and compute tray designs to OCP via MGX, with MGX 1.2 adding blind-mate liquid cooling, 5,000 A busbar, and 19-inch support for racks up to 250 kW.
Baseten's Gradium TTS deployment reaches a median 214 ms time-to-first-audio on Coval's benchmark, using Kyutai's Delayed Streams Modeling and GPU optimizations like kernel fusion and CUDA Graphs. The company also details how its delivery network cuts cold starts for bursty voice traffic.
NVIDIA details RTX Spark laptop software ecosystem at launch, including agent apps, Nemotron 3.5 Bolt 74B, PAIR release, Adobe optimizations, Broadcast 2.3, and Windows on Arm developer tools.
Red Hat compares vLLM's PagedAttention and SGLang's RadixAttention for serving open weight models, with independent benchmarks showing similar throughput and latency across workload shapes.
Baseten partners with Runway to offer Gen-4.5 and Aleph 2.0, including fine-tuned versions, in single-tenant environments with dedicated GPU capacity and autoscaling.
NVIDIA released the full Run:ai platform as open source on October 13, 2026, as part of the DSX AI Factory Platform. The release includes four independently adoptable components, with KAI Scheduler contributed to CNCF as a Sandbox project.
NVIDIA reports Nordic AI cloud capacity will reach one gigawatt by end of 2027, with a Swedish consortium launching a shared supercomputer and multiple enterprises adopting NVIDIA-based AI tools.
NVIDIA's AI Cluster Runtime v1.0 introduces version-locked recipes, signed validation evidence, and a compatibility contract for GPU Kubernetes clusters, with integrations from Pulumi and Mirantis.
AMD published a validated recipe for serving the 744B-parameter GLM-5.3-FP8 model on a single 8-GPU MI300X node using DP8+EP8, reporting 147% higher output throughput than TP=8 on a long-context workload.
MLX v0.32.4 brings 1-bit affine quantization on Metal, new FFT functions, Python 3.15 support, and dozens of kernel and correctness fixes for inference workloads.
Red Hat AI Inference 3.5 brings the MaaS governance layer to Azure Kubernetes Service, adding API key validation, rate limiting, and subscription control to models served through vLLM and KServe on non-OpenShift clusters.
Red Hat's PeopleMesh quickstart shows how to extract structured data from resumes using Docling and Granite4:3B, then match people across skills and interests with natural-language queries on OpenShift AI.
Modular published the cohort of its Community Grant Program on October 9, 2026, naming six open-source projects that will receive small grants to build Mojo and MAX libraries. The company said it received far more strong proposals than it could support.
Red Hat engineers describe how they connected three MCP servers to RHEL, Satellite, and Lightspeed in a Summit lab, including client configuration, authentication, and model selection lessons.
Red Hat's migration toolkit for applications 8.3 is generally available, introducing multi-agent code modernization, direct PVC transfers, and Helm-based generators for OpenShift. The release also serves as the official transition path for the retiring migration toolkit for containers.
Apple researchers ran a week-long study with Wizard of Oz probes to see how people define their own machine learning phenomena, identifying four sites where users negotiate ontological boundaries in personalized sensing systems.
Arm's September 2026 roundup highlights new mobile chips, neural graphics, chiplet connectivity, and on-device AI optimization, with a focus on agentic AI and physical AI across the ecosystem.
AMD's ROCm 10.1 release targets data-movement bottlenecks with hipFILE async and batch I/O, adds NUMA-aware host memory allocation, and introduces a unified ROCm CLI for installs and monitoring.
vLLM v0.31.0 introduces a weight-cache daemon for fast engine restarts, DeepSeek-V4.1-Flash performance work on SM100, new scheduling controls, and per-request multimodal kwargs gated behind a trust flag.
Apple researchers show that adding language discrimination during pretraining helps bilingual HuBERT models match monolingual performance on phone, lexical, and prosodic measures, with the biggest gains when applied early.
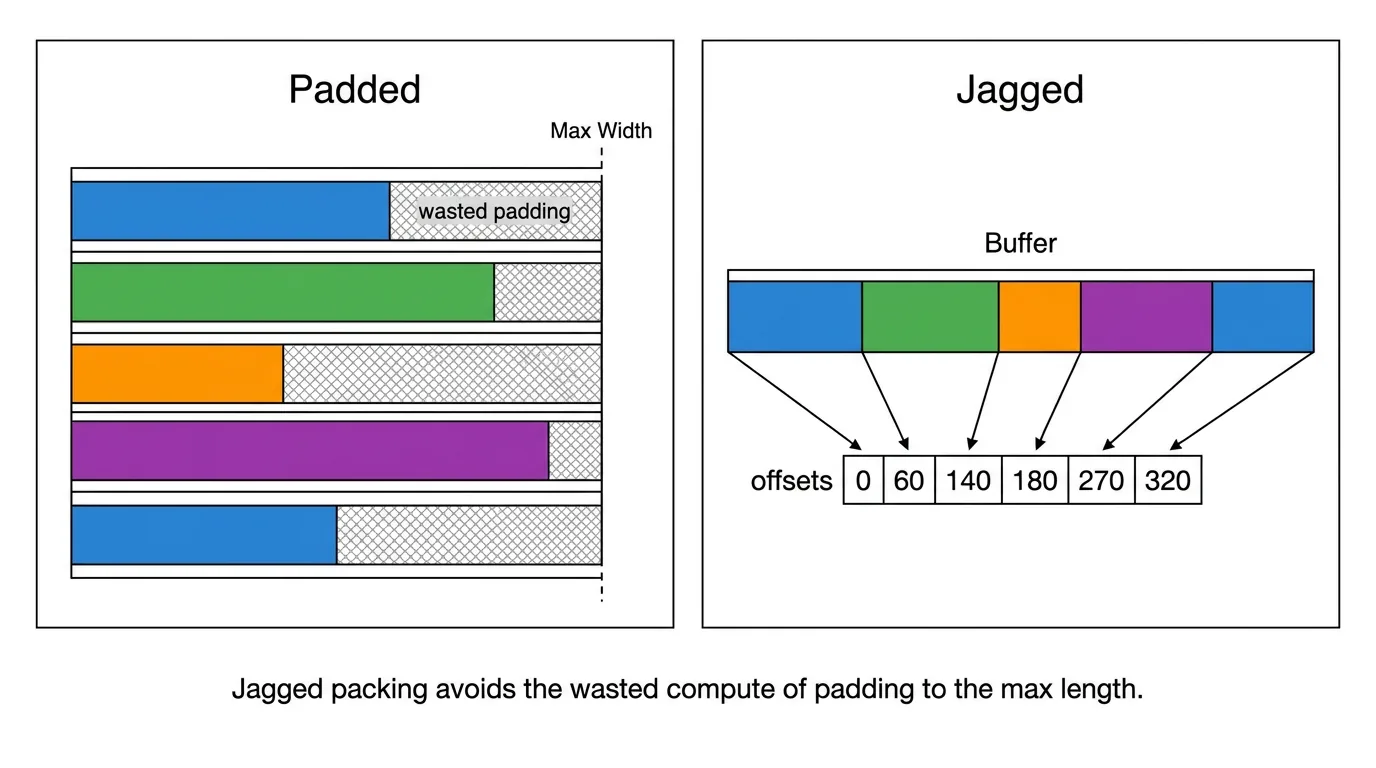
Meta's TLX-based Jagged Flash Attention kernel for GEM outperforms FlashAttention-4 by ~13% forward and ~50% backward on B200, with 3x less code than CuteDSL.
AMD's AIM containers now offer a unified deployment experience across Radeon, EPYC, and Instinct hardware. Dry-run and list-profiles commands let you preview profile selection before starting a server, with automatic tuning of engine arguments and environment variables.
AMD's TraceLens Agent turns raw PyTorch profiles into prioritized, evidence-backed optimization reports, using sub-agents for compute, system, and fusion analysis with guardrails for reliability.
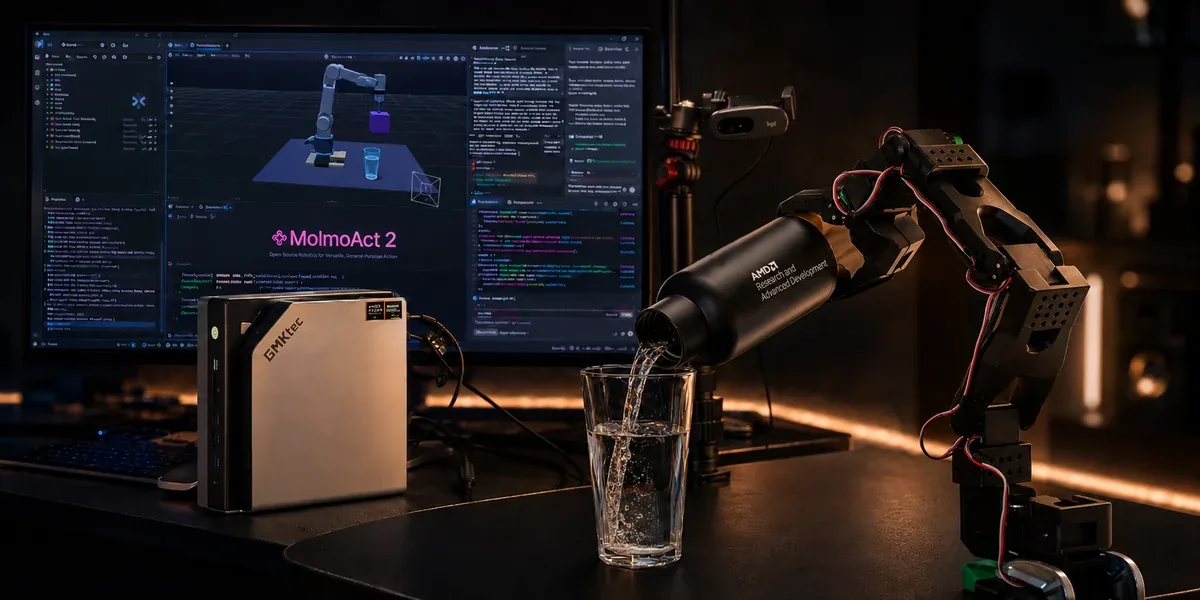
AMD shows a vision-language-action model driving robot arms from a browser on a single Ryzen AI Max+ 395 mini PC. The tutorial covers zero-shot transfer across arms, real-time planning, and LIBERO evaluation using the Ryzers container framework.
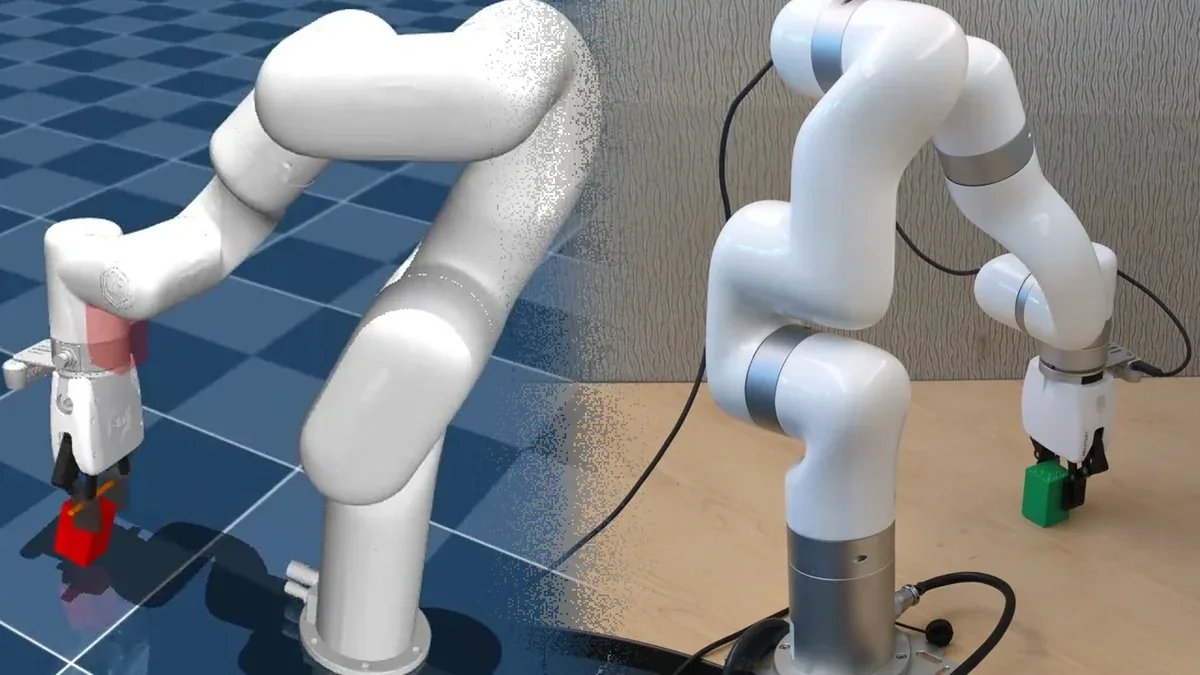
AMD trained a pick-and-lift policy for a UFactory XArm-6 in MuJoCo on Instinct GPUs and transferred it zero-shot to the real robot, with perception on a Ryzen AI 300 Mini-PC.
The llm-d v0.10.0 release shifts inference image builds to upstream vLLM, deprecates its CUDA and AWS images, and introduces a two-registry system with signed production images and unsigned PR builds.
Fireworks introduces a GLOBAL deployment option that lets a single endpoint draw GPU capacity from multiple regions, with scheduling kept off the request path. Production signals show higher success rates for multi-region workloads, though the company notes these are observational, not causal.
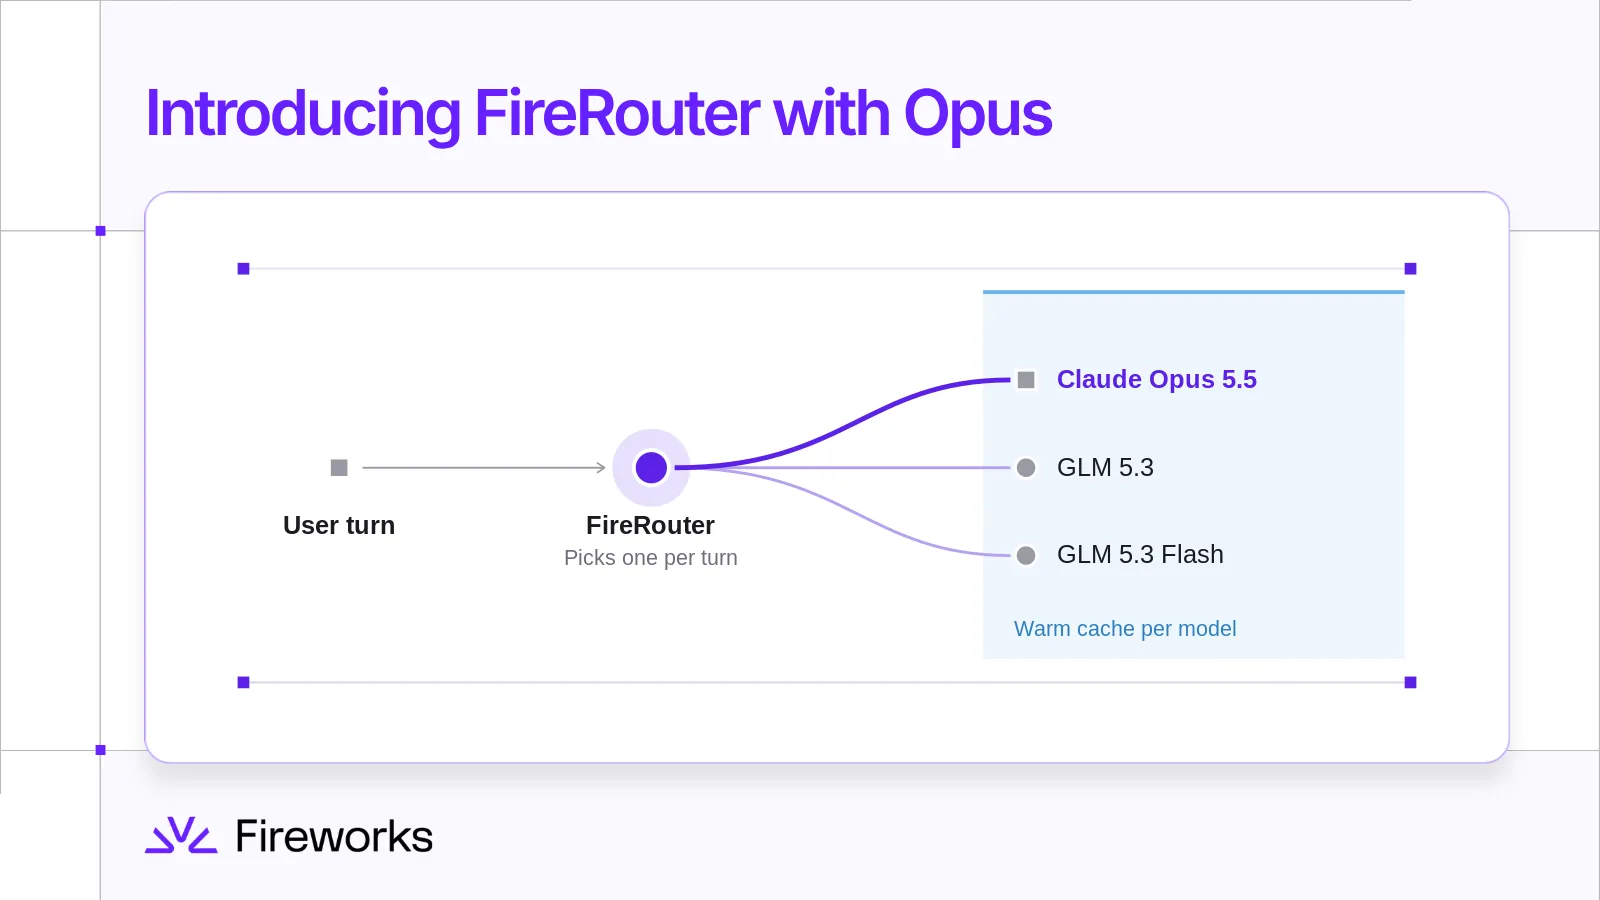
Fireworks AI's FireRouter with Opus routes coding turns among Opus 5.5, GLM 5.3, and GLM 5.3 Flash, cutting costs 57% in internal tests while retaining 98.1% of Opus-only accuracy. It is available as a CLI tool or serverless endpoint.
Fireworks' ARCv3 compressor cuts BF16 weight update deltas to 0.19% of original size, nearly half of ARCv2, enabling cross-region RL rollout fleets to stay in sync over ordinary network links.
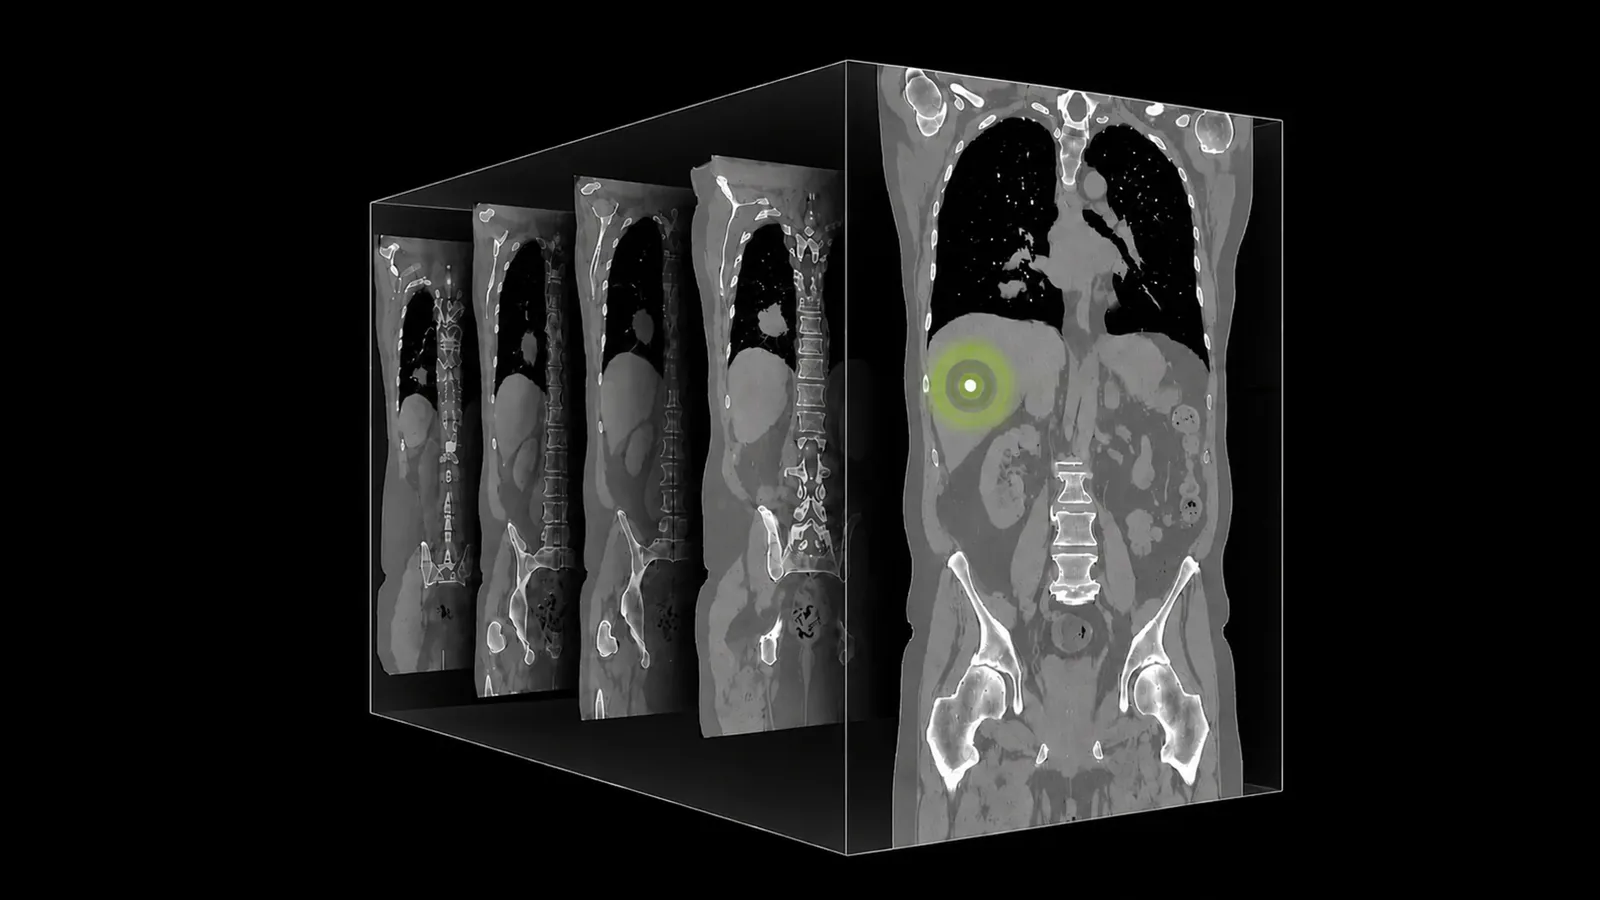
NVIDIA introduces NV-Reason-CT, an open 3D vision language model for CT scans that generates structured reports and radiologist-style reasoning, achieving state-of-the-art results on the CT-RATE benchmark.
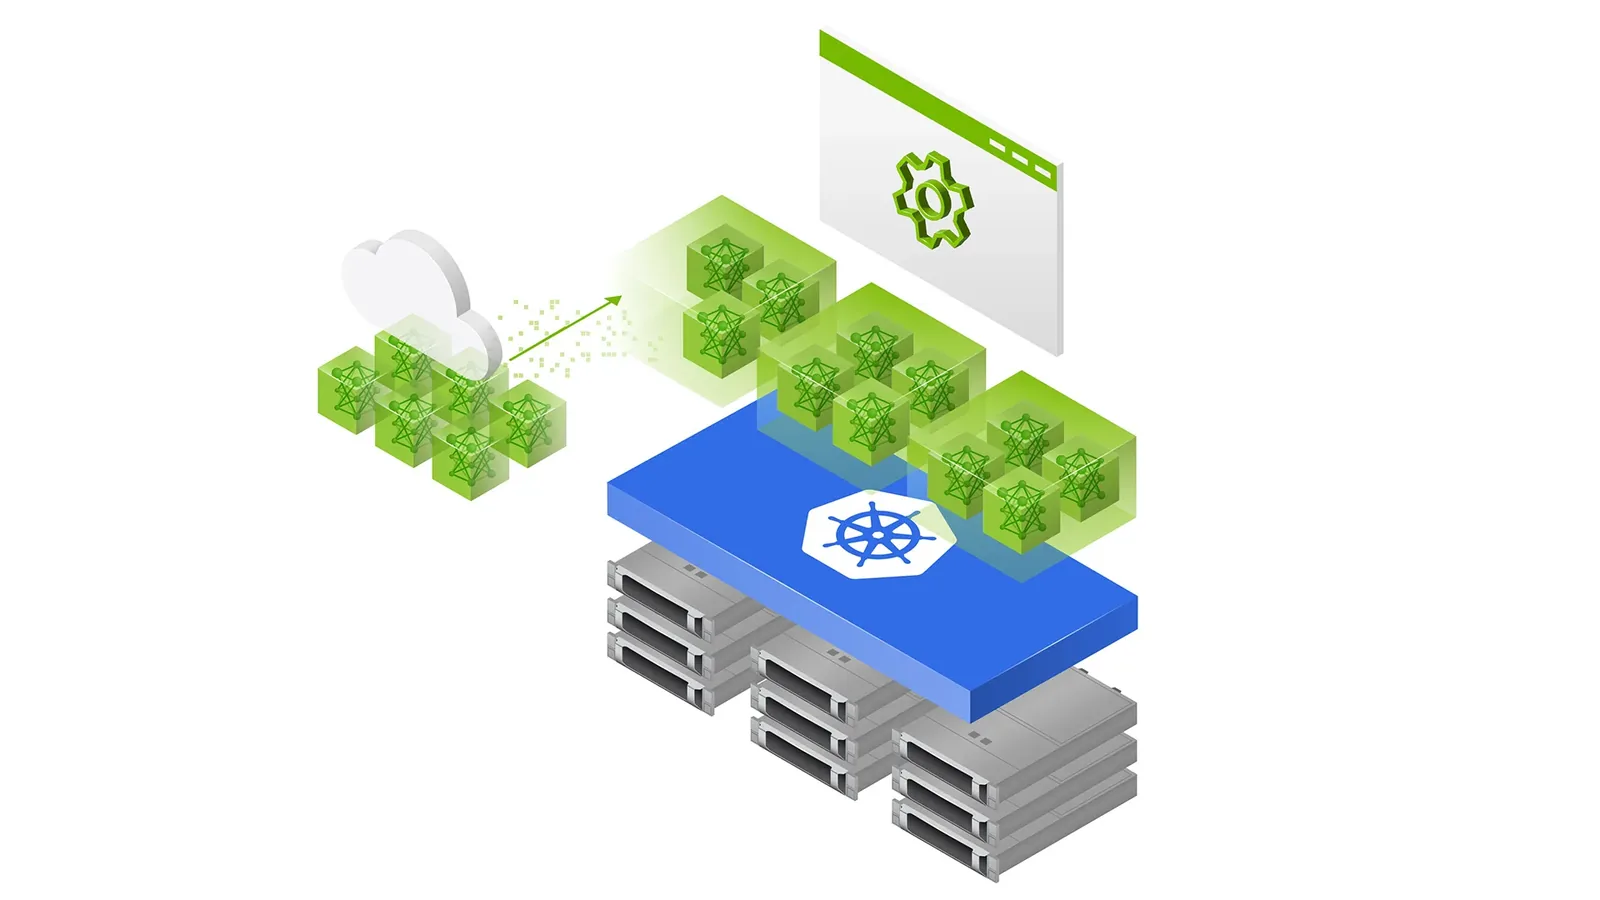
NVIDIA introduces NodeWright, an open-source Kubernetes-native package manager that declaratively configures and updates host OSes across GPU clusters, with progressive rollout strategies and workload-aware disruption handling.
NVIDIA's Cluster Readiness Engine (NVCRE) runs distributed workloads across topology-aware node groups to catch slow GPUs, degraded links, and routing issues before production AI jobs land. It automates fault isolation, cutting debugging from days to minutes.
Together AI shows how to fine-tune a 4B classification model on 37,840 examples for about $17, then deploy it to a dedicated H100 endpoint and query it with JSON input and output.
NVIDIA reports that confidential computing on eight B200 GPUs retained 96.1% to 98.2% of baseline throughput for DeepSeek-R1 inference, with per-token latency overhead between 1.2% and 4.3% across concurrency levels 1 through 16.
NVIDIA's Isaac ROS 5.0 uses the CUDA buffer backend for rosidl::Buffer to move GPU-resident payloads between nodes without host copies, with CPU fallback for incompatible peers. An AI agent skill automates the migration audit and refactor.
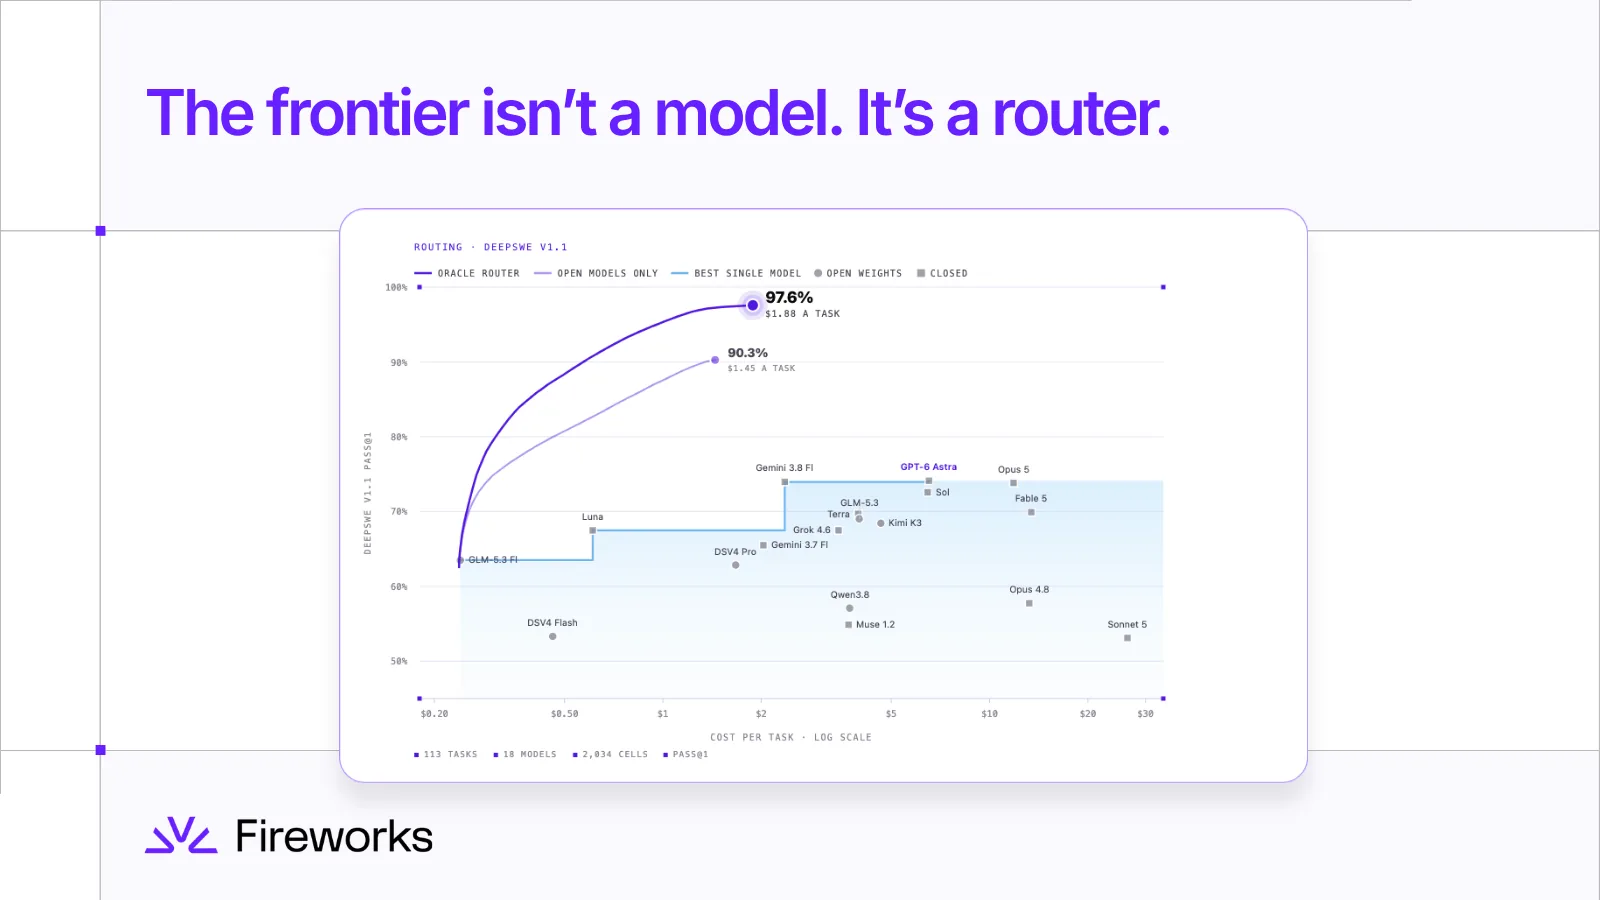
Fireworks ran all 18 models on every DeepSWE task and found an oracle router reaches 97.6% at $1.88 per task, beating the best single model by 23 points at a third of the cost. The company says the real challenge is predicting which model to use before the outcome is known.
A global fintech moved its coding assistant to Together AI's Dedicated Model Inference, running GLM-5.2 on 56 B200 GPUs. The migration fixed bursty traffic queues and gave the team self-service scaling and model updates.
NVIDIA's Vera Rubin NVL72 preview results in MLPerf Inference v6.1 show up to 3.7x higher Qwen3-VL throughput and 2.5x higher DeepSeek-R1 throughput versus GB300 NVL72, with software gains from v6.0.
NVIDIA's TileGym repository now includes an AI agent skill that ports cuTile Python and Triton-TileIR kernels to cuTile Rust, achieving 99.5% of Python performance on average across 24 operators.
The AI Energy Management Alliance (AEMA), founded by Emerald AI, Google, and NVIDIA, aims to make data centers dynamically adjust power use based on grid conditions, enabling faster AI expansion and lower environmental impact per watt.
NVIDIA says Groq 3 LPX uses cycle-exact scheduling to predict current demand, enabling PEP and CPS to cut voltage droop by over 60% and reduce guardband, improving performance per watt for high-interactivity inference on Vera Rubin.
NVIDIA details how NVLink 6 combines lightweight FEC, physical layer retry, credit-based flow control, and software recovery to keep AI factories running through signal errors and link failures.
Together AI expanded its fine-tuning service with support for new open-weight models, live experiment tracking, expert-layer LoRA adapters, early stopping, dataset inspection, and price reductions of up to 70% on selected models.
NVIDIA's BioNeMo Inference Runtime accelerates biomolecular structure prediction on GPUs, folding 58.5K residues per GPU-hour with Boltz-2, a 2.9x improvement over torch-compiled open-source code. The tool also processed 31 million complexes for the AlphaFold Database.
NVIDIA reports that its NIM 2.0.12 serving stack delivers 1,997 tokens per second on a 4xB200 system at a 50 TPS per user target, up from 718 tokens per second without optimizations, enabling more concurrent users at the same interactivity.
Together AI's kernels team adapted ThunderKittens for NVIDIA Vera Rubin NVL72, using wider tensor core K steps, larger tensor memory and shared memory, plus a B-side collector, to push NVFP4 GEMMs past 22 PFLOPS.
NVIDIA post-trained Nemotron 3.5 Lightning on captured allocation decisions to reach 86.7% accuracy, beating larger models. The workflow uses Palantir Foundry and cuOpt to codify human planner expertise.
NVIDIA Dynamo's encode-prefill-decode disaggregation separates vision encoding from LLM stages, delivering up to 5x faster time to first token and 7x faster end-to-end response for image-heavy workloads. Gains depend on media load, output length, model size, and traffic mix.
NVIDIA's CUDA Toolkit 13.4 brings Windows on Arm support, a preview of the Rubin architecture, MPS V3 for shared GPU control, and new CUDA Python features for texture and managed memory.
Alibaba Cloud and Cambricon became Platinum members and Ant Group Gold member of the PyTorch Foundation, announced at PyTorch Conference China 2026 in Shanghai. Keynotes from these firms and Huawei covered the open AI stack from chips to deployment.
NVIDIA's NemoClaw recipe for a memory-driven Chief of Staff agent stores knowledge in Markdown and judgments in SQLite, using an intent gate and audit trail. The self model lifts overall accuracy to 90.9% from 82.8% on the Agent Memory Benchmark versus an agentic RAG baseline.
NVIDIA shows how Nemotron 3.5 Lightning and Qwen3.8-27B run on Jetson AGX Thor and Orin, with NVFP4 quantization and speculative decoding delivering up to 6.28x decode throughput speedup over BF16.
NVIDIA describes a central identity gateway pattern for federated Kubernetes that separates session ownership from request enforcement, cutting repeated login events by 55% across internal platforms in AWS and OCI.
At IFA 2026, NVIDIA announced the Personal AI Router (PAIR) for distributing inference across local PCs, up to 1.9x faster llama.cpp throughput, and October availability of RTX Spark Windows PCs from Lenovo and Acer.
NVIDIA's PAIR beta proxies Ollama and LM Studio to schedule independent inference requests across paired local systems, cutting a five-subagent demo from 18 minutes to 8 minutes 48 seconds on a three-device cluster.
NVIDIA's cloud gaming service adds 28 titles in September, led by NBA 2K27 with DLSS 5 3D-Guided Neural Rendering, available to Ultimate members on RTX 5080 rigs. The Blood of Dawnwalker and Onimusha: Way of the Sword also launch on the platform.
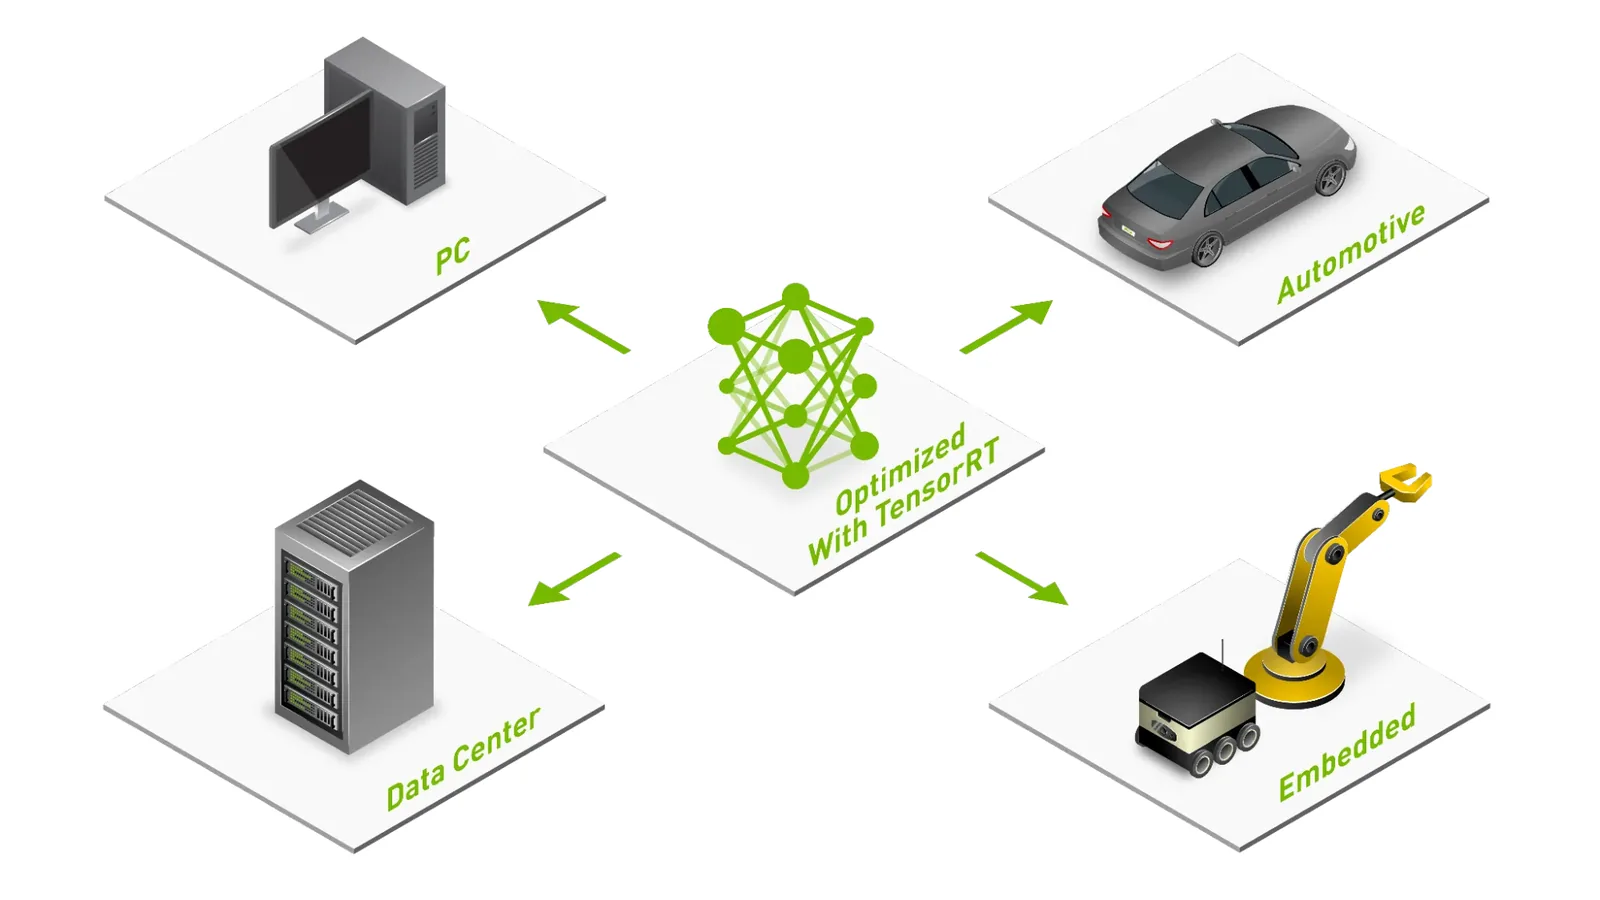
NVIDIA's TensorRT Model Connect builds a model bundle with a Python CLI, then loads it in C++ without Python at runtime. The open-source project targets faster inference than torch.compile for supported workloads.
NVIDIA's Vera CPU, its first custom processor for agentic AI, is now shipping to AWS, Oracle Cloud Infrastructure, Anthropic, OpenAI and SpaceXAI. The 88-core chip targets CPU-heavy agent workloads with 1.2TB/s memory bandwidth.
Alibaba's 125B-parameter MoE model with recurrent and sparse attention layers reaches over 16,000 tokens per second per GPU on NVIDIA GB300 NVL72, with day-0 support in SGLang, vLLM, and TensorRT LLM.
NVIDIA's COMPASS workflow uses AI agents to automate validation, scene preparation, residual training, and evaluation for robot navigation policies, with human approval gates and evidence tracking.
NVIDIA's NVLink Fusion and NVHBM memory technology aim to let hyperscalers deploy custom XPUs with up to 30% more bandwidth per stack and 15% lower HBM power use compared with standard HBM4e.
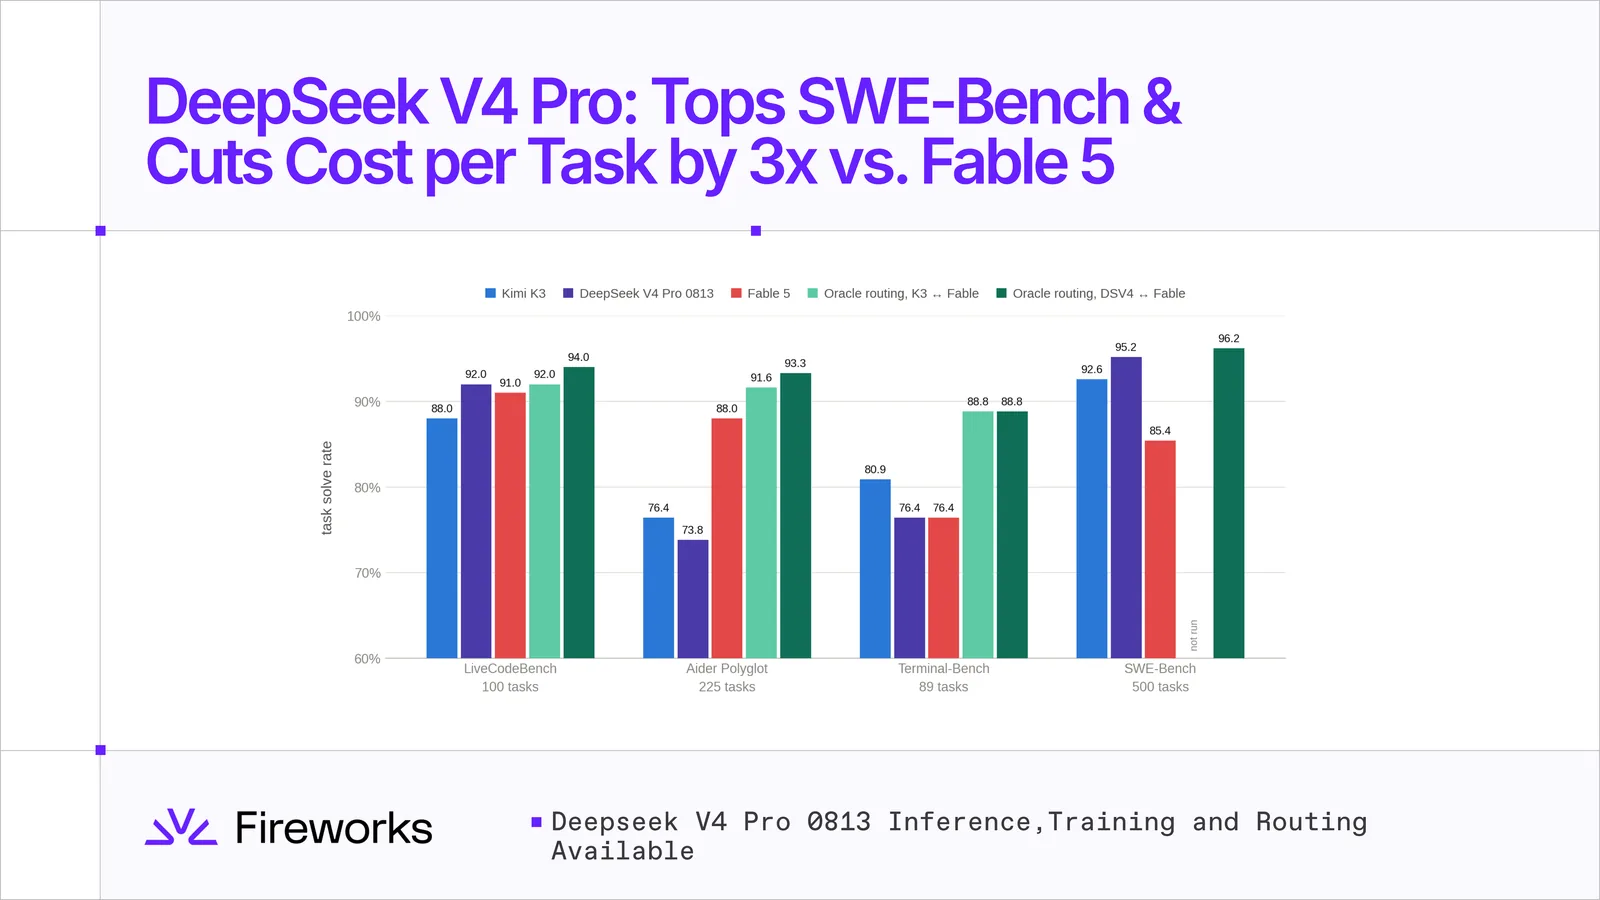
Fireworks AI reports DeepSeek V4 Pro 0813 leads its SWE-Bench and LiveCodeBench runs, cuts cost per solved task versus Fable 5, and pairs better with routing. Training is live.
The PyTorch Ecosystem Working Group welcomed 10 new projects, including RLinf, Miles, SMG, TokenSpeed, and FiftyOne, expanding coverage from reinforcement learning to model serving and multimodal data.
NVIDIA's shadow engine recovery in Dynamo restores LLM serving in 7.3 seconds versus 283 for a cold restart, using a parked engine and shared GPU memory. It's a preview feature for Kubernetes 1.34+ with vLLM support.
NVIDIA's CUDA Python 1.0 milestone brings semantic versioning guarantees to independently released components, with cuda.core 1.0.0 as the shared foundation for devices, streams, and buffers across the Python GPU ecosystem.
NVIDIA details how Spectrum-X Ethernet uses hardware-accelerated control loops and a multiplane topology to handle giga-scale AI workloads, claiming stable training times under multi-tenant congestion and fast failover versus traditional Ethernet.
NVIDIA previews Vera Rubin NVL72 results on SemiAnalysis AgentX, claiming up to 30x higher AI-factory throughput per megawatt than GB300 NVL72 at 160 tokens per second per user. GB300 NVL72 itself shows up to 15x over H200 NVL8 on DeepSeek V4 Pro and 80x on Kimi K3 2.8T.
NVIDIA's AdaptGrow solver reduces SymNMF peak storage from 20n² to 4n² bytes, fitting 100,000 instruments on one GB200 GPU and scaling to one million across 64 GPUs, with auto-configured optimization and structural-break detection.
Together AI reports GLM-5.3 ties Claude Fable 5 on DeepSWE pass@1 while costing $3.99 per rollout versus $21.63. Per $100, GLM-5.3 solves 17 tasks, Claude Fable 5 solves 3. A routing strategy escalates to Claude Fable 5 for 81.1% accuracy at $10.74 per task.
NVIDIA details production-ready training and inference for generative recommender systems, with HSTU and Semantic ID models showing up to 2.38x speedups and 2.14x lower latency on H100 GPUs.
NVIDIA's open-source SkillEvaluator benchmarks verified AI agent skills with static checks and live runs, reporting an average 31-point Skill Lift across 300+ skills, with correctness and effectiveness gains of 41 and 39 points.
NVIDIA's Cosmos 3 Edge, a 4B omni-model, runs natively on Jetson Thor for robot manipulation. Post-trained on the Cosmos3-DROID dataset, it generates action chunks in about 1.53 seconds on Jetson AGX Thor T5000, achieving 22.9% success in closed-loop RoboLab evaluation.
NVIDIA engineers used a coding agent with the Holoscan CLI and HoloHub skills to build an endoscopic tool segmentation dashboard in three iterations, cutting latency by 33.6% and raising throughput by 50.5%.
Together AI's DeepSWE comparison shows DeepSeek V4 Pro 0813 and Claude Fable 5 fail on different tasks, enabling a Pro-first cascade that solves 82.7% of tasks at $8.28 each, beating Fable alone on accuracy and cost.
NVIDIA partners with SB Energy to secure 4.25 GW of capacity at PORTS-Pike in Ohio, with OpenAI as tenant. The site supports multiple GPU generations over 20 years, with potential expansion to 8 GW.
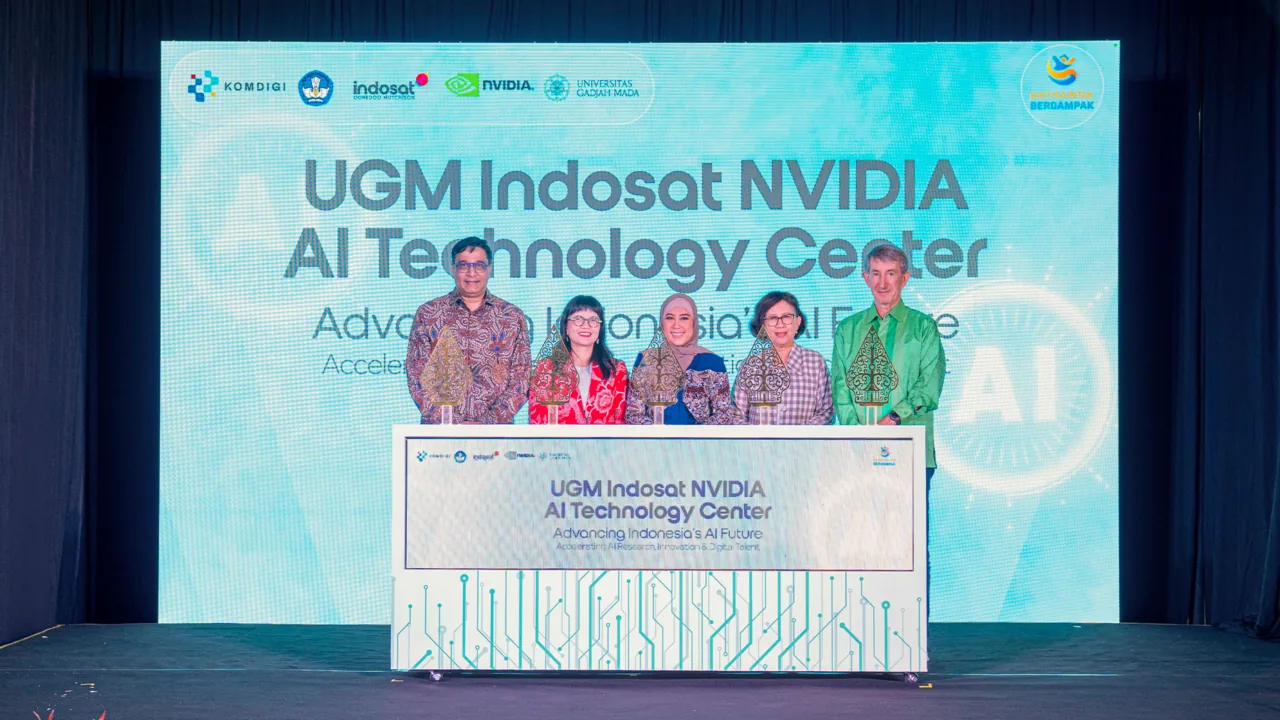
Universitas Gadjah Mada, Indosat, and NVIDIA launched Indonesia's first university-based AI technology center in Yogyakarta, focused on healthcare, agriculture, and disaster response.
AMD and PyTorch engineers upstreamed FP8 training optimizations for AMD Instinct GPUs into TorchTitan and TorchAO, delivering throughput gains on dense and MoE models through kernel fusion and format correctness fixes.
Fireworks AI fitted Jacobian Lens probes on Kimi K3 and Qwen3.5-9B, finding task-related vocabulary in hidden states before it appears in output. The method transferred across architectures, with 19 of 20 word lists matching on Qwen.
Alibaba's 2.4T-parameter MoE model with 95B active parameters runs over 4K tokens per second per GPU on NVIDIA GB300 NVL72 in FP8. NVIDIA provides recipes for SGLang, vLLM, Dynamo, and NIM, plus NeMo AutoModel for fine-tuning.
JetPack 7.2.1 introduces PyNvVideoCodec 2.2 for hardware video encode/decode, agentic video skills for workflow automation, and T3000 emulation on T5000 hardware.
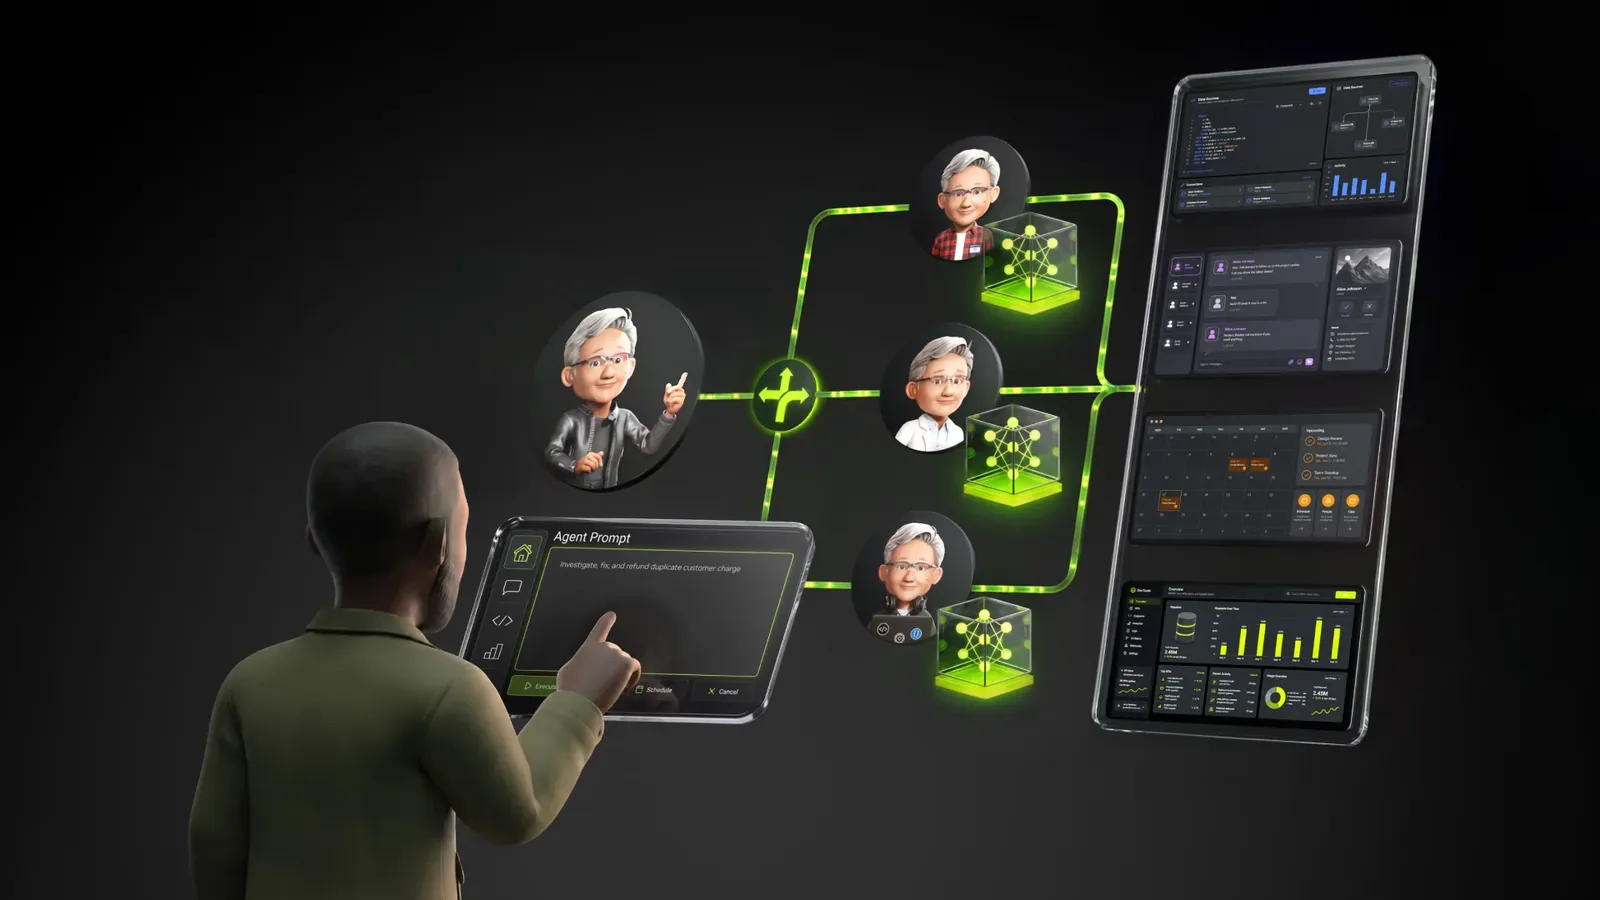
NVIDIA released Nemotron 3.5 Lightning, an open 30B MoE model with 3B active parameters, plus NeMo Switchyard for routing tasks between frontier and execution models.
Meta introduced Muse Glimmer, an open-weight 30B model for on-device agentic AI, with ExecuTorch support for NVIDIA GPUs and Apple silicon. Prebuilt PTE artifacts are available, enabling text and image inputs, DFlash speculative decoding, and 128K+ token context.
Meta's 30B dense model Muse Glimmer runs at over 20K tokens per second on a single NVIDIA GPU, fitting in VRAM for local agentic workflows. NVIDIA outlines deployment paths across RTX, DGX, and Jetson platforms.
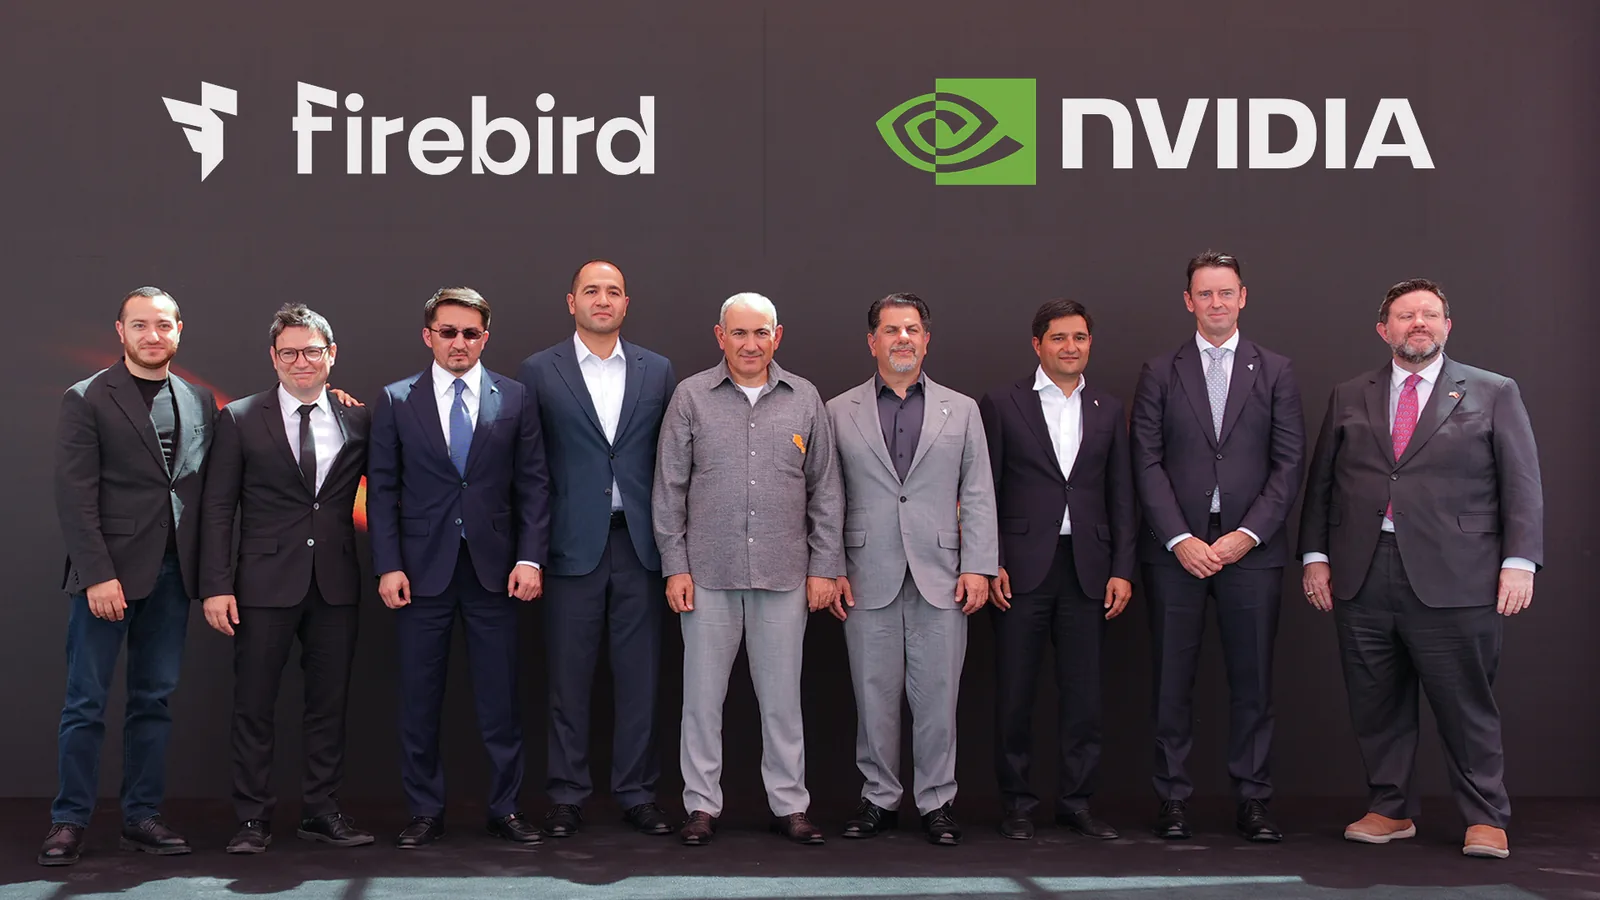
Firebird launched the CIS region's largest AI factory in Armenia, with plans to install over 70,000 NVIDIA Rubin and Blackwell GPUs by end of 2027. The site targets 300 MW power capacity and early customer Perplexity will use the infrastructure for its AI agent platform.
NVIDIA's Alpamayo 2 Super combines a 32B reasoner with a 2B diffusion action expert to output trajectories, reasoning traces, and auto-labels. Open-loop and closed-loop results show improvements over Alpamayo 1.5 Nano, with weights on Hugging Face.
NVIDIA's Vera CPU, embedded in the BlueField-4 STX storage processor, outperforms a benchmarked x86 CPU in encryption, compression, integrity checking, and Reed-Solomon recovery, according to vendor benchmarks.
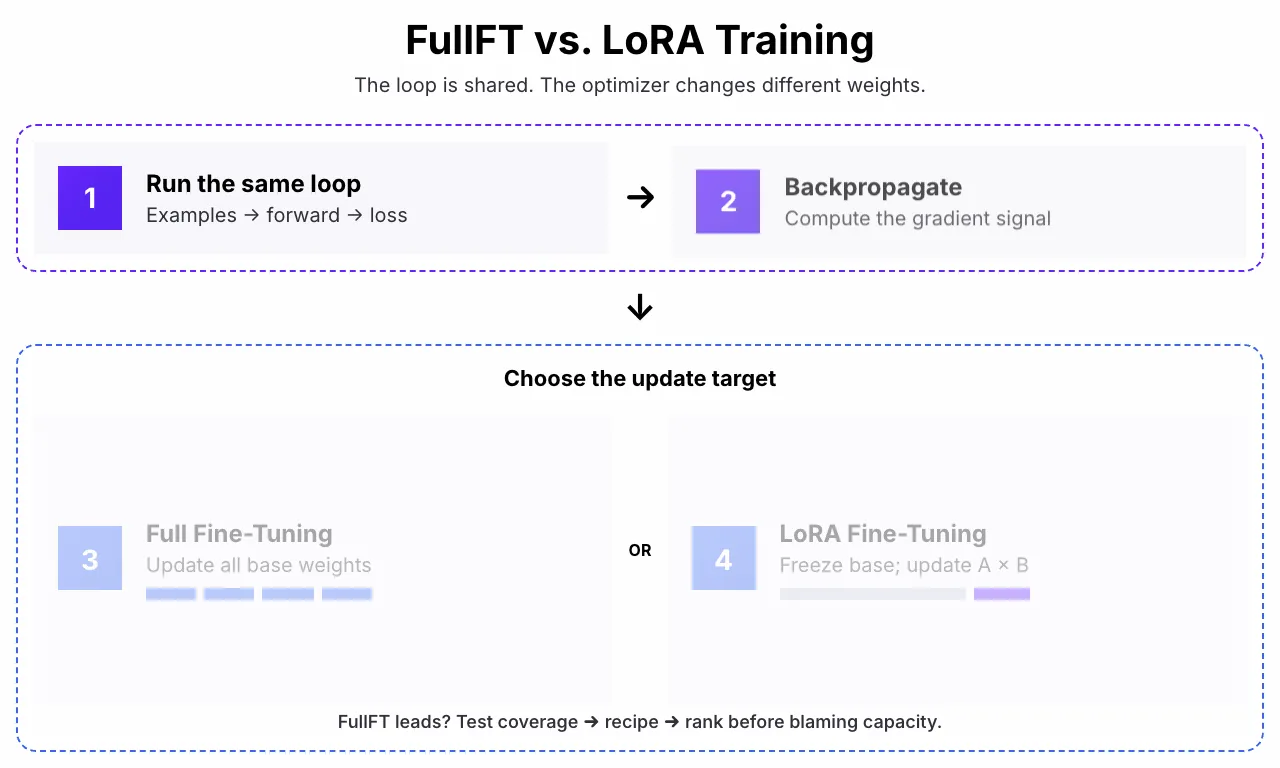
Fireworks AI ran controlled experiments on Qwen3.5-9B to isolate whether data coverage, optimization, or adapter rank explains LoRA's gap to FullFT. The results show that tuning the learning rate or broadening data often closes the gap, while rank matters only in some tasks.
NVIDIA shares four debugging cases from partner clusters where configuration choices in the kernel, hypervisor, BIOS, and NCCL compounded into 8-12% throughput gaps, and the tuning changes that closed them.
NVIDIA's AI Red Team found that access control, code execution, network egress, and secret handling are the recurring weak points in AI agents. The team recommends deterministic controls outside the model's control plane.
NVIDIA's nvmath-python v1.0 wraps CUDA-X math libraries in a Pythonic API, supporting CPU, GPU, and distributed execution. It introduces a universal sparse tensor and stateful APIs that amortize planning costs across repeated runs.
Together AI and academic collaborators introduce ThunderAgent, a program-level scheduler that treats agent workflows as schedulable units, cutting KV cache thrashing and delivering up to 2.5x single-node throughput and 2.4x speedup on 8 nodes.
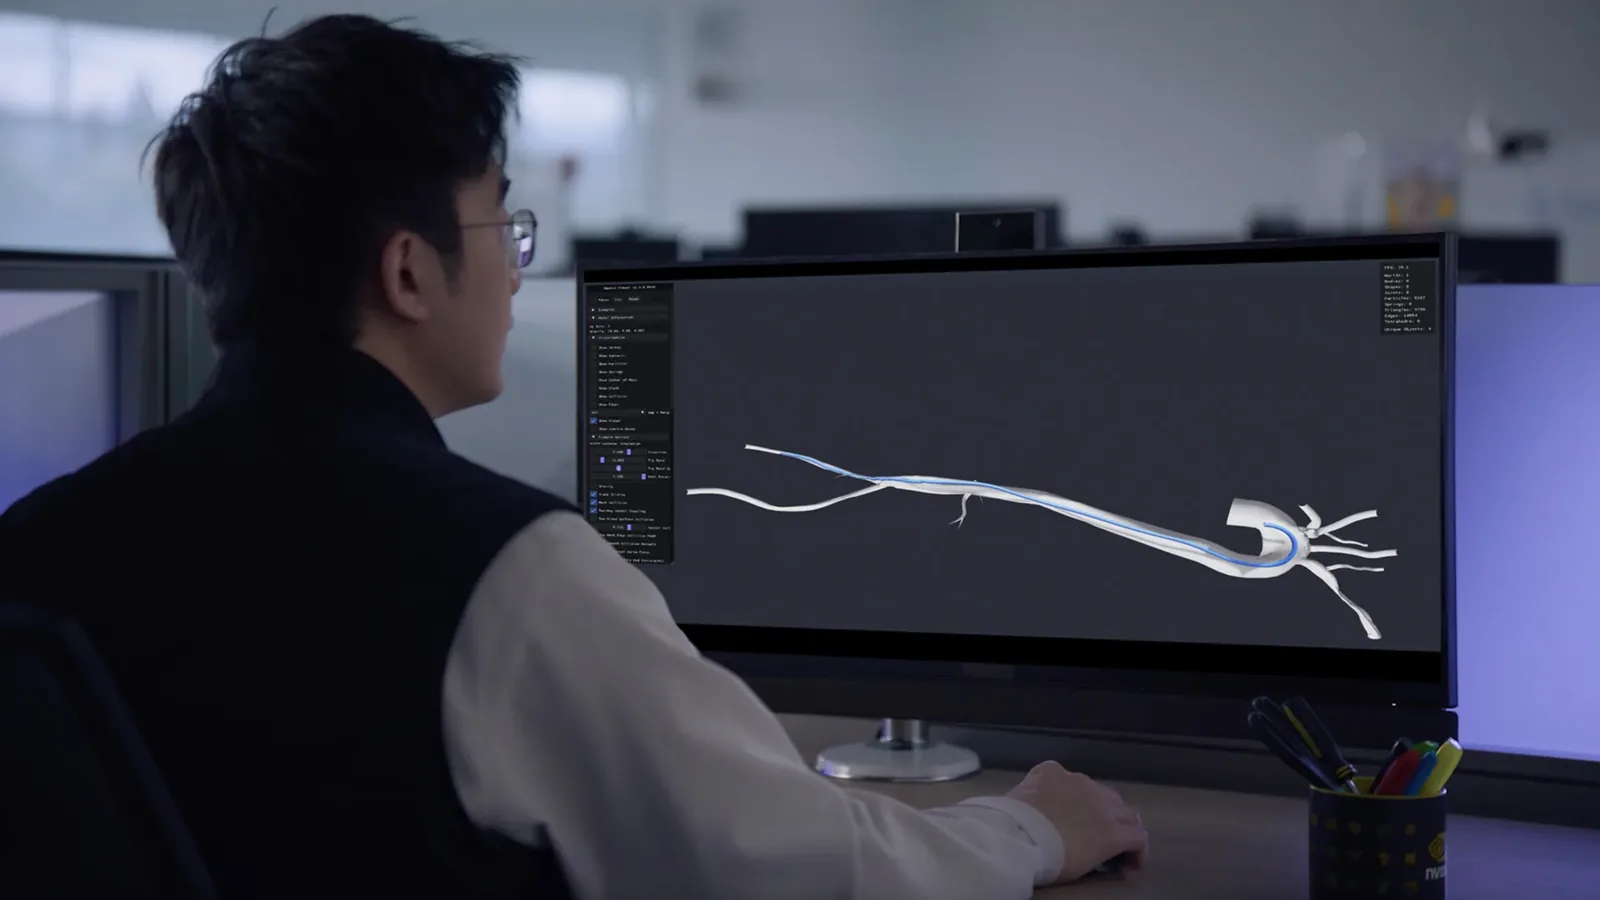
NVIDIA released GPU-native simulation modules for catheter navigation and soft-tissue surgery, plus generative world models, to train healthcare robots with reinforcement learning at scale.
NVIDIA highlights its Jetson lineup for edge AI and robotics, from the 67 TOPS Orin Nano Super developer kit to the 2070 FP4 teraflops AGX Thor with 128GB of memory, with example projects for each tier.
vLLM v0.26.0 introduces the Inkling model family with full support, DeepSeek-V4 performance kernels across vendors, fp32 lm_head via head_dtype, and per-KV-cache-group attention backend selection.
NVIDIA's Ising Calibration 1.5, a 31-billion-parameter vision language model, interprets quantum processor diagnostics and recommends tuning actions. It improves 86.68% over its predecessor with in-context learning and now ships in an NVFP4-quantized version for single-GPU or DGX Spark deployment.
NVIDIA's ModelExpress (MX) selects the fastest available source for model weights, prioritizing GPU-to-GPU P2P RDMA transfers via NIXL over redundant downloads from remote storage. It also reuses kernel compilation caches and coordinates fleet-wide downloads to cut cold start times dramatically.
NVIDIA and Prime Intellect Lab show a three-step workflow to customize Nemotron 3 Nano with hosted reinforcement learning, producing a downloadable LoRA adapter. Baseline accuracy on 32 math problems rose from 21.9% to 90.6% after 100 training steps.
Together AI's updated Dedicated Model Inference platform adds stable endpoints, canary and blue-green rollouts, A/B and shadow testing, and autoscaling. A closed beta for custom training with RL and SFT is also open.
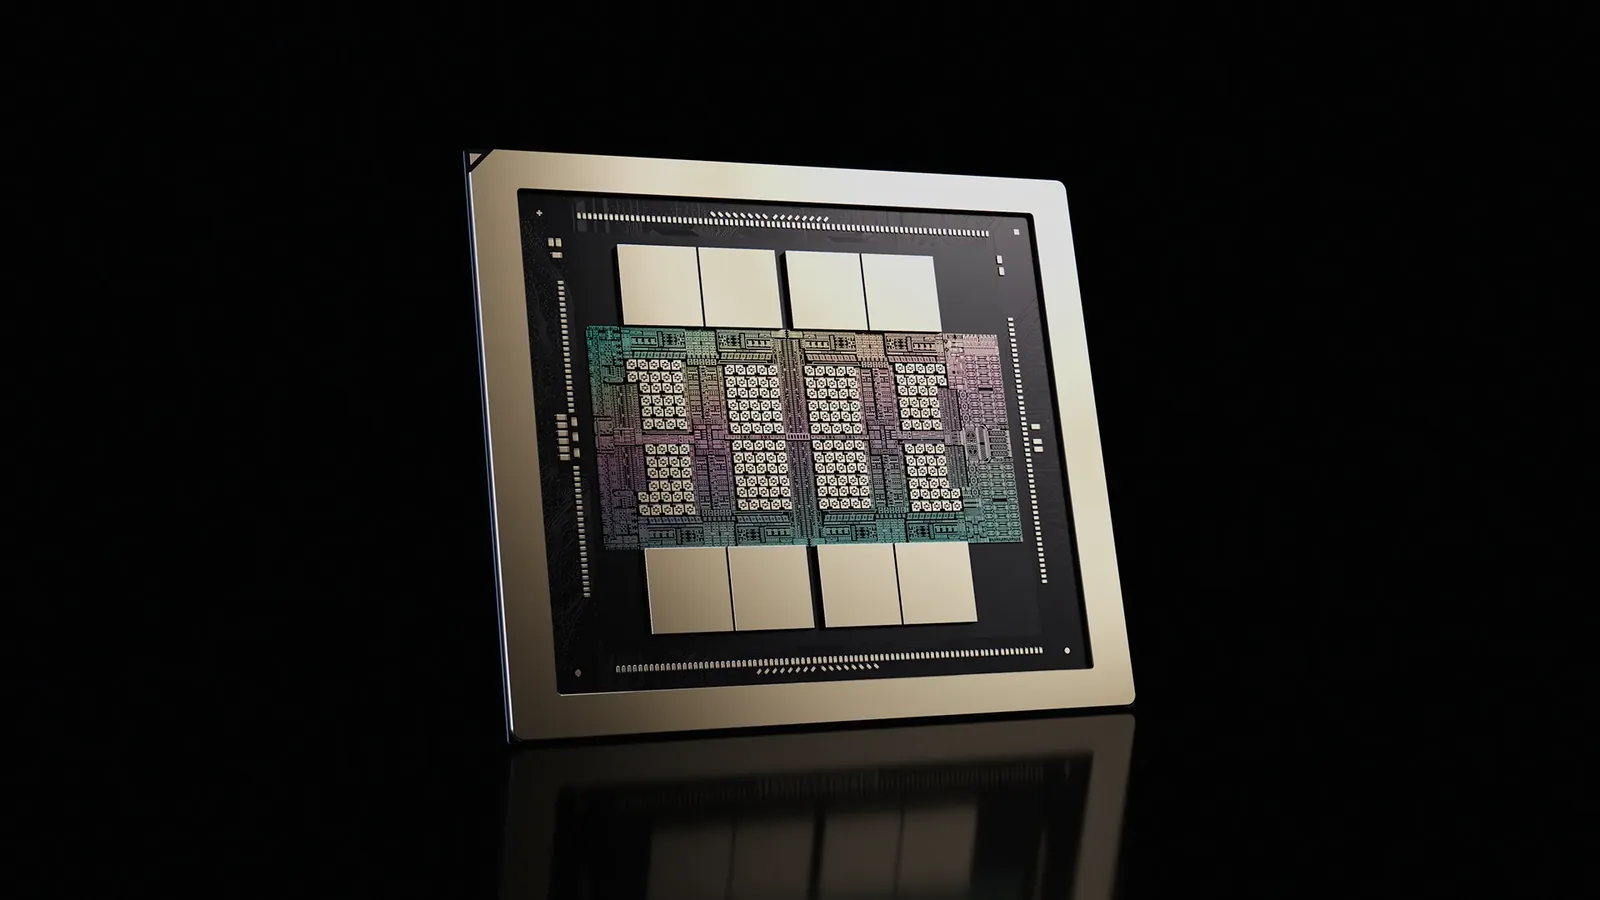
NVIDIA's Rubin GPU targets agentic AI with up to 10x throughput per energy versus Blackwell, 288 GB HBM4, 50 petaflops NVFP4, and NVLink 6. The architecture adds TMA descriptor updates, doubled K-dimension Tensor Cores, and sparsity for long-context attention.
NVIDIA published specifications for sixth-generation NVLink, including 3.6 TB/s per GPU bandwidth, 260 TB/s rack-level throughput, and 130 TFLOPS in-network compute for the Vera Rubin NVL72 platform.
NVIDIA positions Vera Rubin as a platform for continuous post-training workloads in agentic AI, claiming it can train the largest models with one-fourth the GPUs of Blackwell. The post details benchmarks for Nemotron 3 Ultra and partner deployments from Prime Intellect, Perplexity, and Together AI.
NVIDIA's BlueField-4 DPU integrates a 64-core Grace CPU, LPDDR5X memory, and PCIe Gen6, delivering up to six times the compute of BlueField-3. It offloads networking, storage, and security to boost GPU utilization and cut inference latency.
NVIDIA's NemoClaw orchestrates the Video Search and Summarization and RAG blueprints to turn video analysis into coordinated actions like ticket creation and workflow routing, with a healthy eating coach demo creating Jira tickets from meal prep videos.
NVIDIA DeepStream 9.1 introduces AutoMagicCalib and Multi-View 3D Tracking to fuse detections from multiple cameras into a shared 3D coordinate system with consistent object IDs, plus agentic skills for natural-language deployment.
NVIDIA's nanousd-labs project uses AI agents to generate a lightweight USD runtime directly from the USD Core Specification, offering a stable C ABI and spec-compliance validation. The approach lets developers tailor runtimes to specific memory, performance, or ABI needs without adapting large existing codebases.
SGLang v0.5.15 ships GLM-5.2 NVFP4 production tuning on Blackwell, makes Spec V2 and Breakable CUDA Graph defaults, and adds DeepSeek-V4 prefill optimizations plus new model support.
NVIDIA's guide explains how hidden dimension, intermediate projection, and layer count shape throughput and latency, with rules for near-square weights, 128-aligned dimensions, and NVFP4 quantization.
NVIDIA's BioNeMo Agent Toolkit accelerates each stage of co-folding: GPU-based MSA search, cuEquivariance kernels, optimized OpenFold3 NIM inference, and Fold-CP context parallelism for multi-GPU scale-out.
NVIDIA describes replacing CPU-orchestrated MPI with NVSHMEM-based GPU-initiated remote memory access in GROMACS, fusing pack, put, and wait into single kernels to remove 12 blocking syncs per timestep and improve scaling.
NVIDIA's NeMo-based iterative pipeline produced 502,536 unique financial news headlines across 13 categories, using global deduplication and dynamic category weighting to maintain novelty and balance.
NVIDIA says Nemotron 3 Ultra, tuned via LangChain's Deep Agents harness, beats open models on accuracy and matches closed models on business tasks, at 10x lower inference cost per run.
NVIDIA and LangChain show how a harness profile with a middleware fix resolves all three read_file pagination failures and raises the evaluation score from 94 to 96 out of 127, without fine-tuning.
NVIDIA introduces a revenue-sharing and credit-support model that lets AI clouds procure its infrastructure, with Sharon AI and Firmus among the first partners building DSX AI factories.
NVIDIA reports that enabling Confidential Computing on HGX B300 with a Qwen 3.5 model costs roughly 1% to 8% in throughput and time per output token, with optimizations in FlashInfer and SGLang reducing launch overhead.
NVIDIA outlines a practical reinforcement learning with verifiable rewards workflow, using GRPO and tools like NeMo RL and Gym, to specialize open models for domain-specific agent tasks.
Together AI announced an $800 million Series C led by investors including NVIDIA and Aramco Ventures, with commitments for over 500 MW of compute capacity. The company cites 6x to 20x cost reductions for customers using open-weights models in production.
Together AI had nine papers accepted to ICML 2026 in Seoul, covering agent serving, test-time reinforcement learning, long-context training, and Mixture-of-Experts latency. The papers include DSGym, ThunderAgent, TTT-Discover, RARO, V1, Aurora, Untied Ulysses, and Opportunistic Expert Activation.
NVIDIA's GQE reference architecture executes SQL on GPUs with cuDF, nvCOMP, and nvSHMEM, using pipeline parallelism, hybrid compression, and zone-map pruning. On a GB200 GPU it completes all 22 TPC-H queries in 9.0 seconds, a 7.5x speedup over DuckDB on dual-socket AMD Turin CPUs.
Fireworks AI released GLM 5.2 Fast, a serverless serving path that runs about 2x faster than its Standard route on the same model, with no reserved GPUs. The company details how it splits expert and attention sharding, uses sparse attention, and keeps cached input tokens at $0.14 per 1M.
NVIDIA engineers used Nsight Systems and Nsight Compute to optimize the Omniverse NuRec neural reconstruction pipeline, fusing small kernels for a nearly 50x speedup in one function and improving renderBackward occupancy from ~15% to 30-50%.
NVIDIA published a deployment guide for AI-Q 2.0 on Oracle Cloud Infrastructure, using Terraform for OCI resources and Helm for Kubernetes workloads on OKE. The setup creates a working AI-Q endpoint in about 20 to 25 minutes.
Fireworks AI details how Cursor's Composer 2, built on Kimi 2.5, uses distributed reinforcement learning across global clusters, with compressed weight updates and reused inference to cut costs and improve coding performance.
NVIDIA explains how it quantized Nemotron 3 Ultra to NVFP4, cutting model size from 1,121 GB to 352.3 GB. The post details mixed-precision layer assignments, four-over-six block scaling, and AutoQuantize's bit budget search.
PUBG Ally uses a 2 billion parameter Mistral-NeMo-Minitron-2B model on the player's GPU, with a System 1 behavior tree for reflexes and a System 2 language layer for reasoning. KRAFTON details quantization, KV cache reuse, and tool-based grounding.
NVIDIA TensorRT 11.0 introduces native multi-device inference with NCCL collectives and context parallelism strategies. Benchmarks on Cosmos 3 and FLUX.1-dev show DeepSpeed Ulysses delivering the lowest end-to-end latency for long-sequence diffusion workloads.
Fireworks AI now provides managed training infrastructure for GLM 5.2 that keeps training and serving numerically identical, with zero KLD end to end. The service targets reinforcement learning on frontier models, addressing batch invariance and deterministic numerics.
NVIDIA's BEVPoolV3 optimizes BEV pooling for GPUs by classifying the working set as DRAM-bound or L2-resident, then applying different kernel strategies. On RTX A6000 it hits 90.0 µs FP16; on RTX PRO 6000 Blackwell Max-Q it reaches 16.4 µs FP8.
Fireworks AI reports that pairing open-source worker models with a single closed-source review call from Claude Opus 4.8 improves success rates across three benchmarks while cutting inference costs by 19% to 67%.
Together AI's new benchmark tests LLMs on 87 real-world multi-GPU kernel problems. The best model solves 28 correctly, and only 22 beat the PyTorch baseline, showing frontier models still lag on fast kernel generation.
NVIDIA outlines how power costs up to 40% of AI factory OpEx and details system, precision, and scheduling optimizations to improve performance per watt across inference and training.
NVIDIA's DFlash block-diffusion drafter generates multiple candidate tokens in one forward pass, delivering up to 15x higher throughput on Blackwell Ultra for gpt-oss-120b and nearly doubling interactivity over EAGLE-3 on Llama 3.1 8B.
llama.cpp b11623 adds a SIMT implicit GEMM convolution path for AMD GPUs that skips WMMA, with a guard for short reductions. The release also updates build assets and disables KleidiAI on macOS.
Apple researchers show that frame-level activations in pretrained speech encoders can detect code-switching without transcription, using language-selective hidden dimensions. The method reaches a mean F1 of 0.798 across 14 language pairs in CS-FLEURS with a Whisper-small encoder.
Siemens EDA used NVIDIA NeMo Gym to evaluate and refine its Solido Characterization Suite agent for Liberty file generation, raising the composite verification score from about 55% to 95% while cutting agent turns from 155 to 53.
Apple researchers introduce the first tri-modal masked diffusion model pretrained from scratch on text, image-text, and audio-text data, with a new SDE-based reparameterization that removes batch-size tuning.
Apple researchers compared auxiliary-language mixing against hyperparameter tuning across four model scales up to 1.43B parameters, finding mixing improves validation loss and downstream accuracy more, with gains equivalent to 2-13x unique target data.
NVIDIA's cuDF skills for Apache Spark use AI agents to rewrite CPU-bound UDFs into GPU-accelerated equivalents, cutting operator time from 274.55 to 12.78 hours in a 600-billion-row workload.
Ollama Cloud integrates with Fly.io Sprites, letting AI agents in sandboxed Linux VMs call models like kimi-k3 and glm-5.3 without exposing API keys. A gateway adds keys per Sprite, and access is blocked by default.
Ollama's release candidate v0.40.4-rc1 introduces Kev decision scoring to the MLX backend, loading Kev models with FP32 decision heads and release metadata, plus System One scoring with shared-state caching.
NVIDIA and Princeton's Dao AI Lab propose representing SSM state as a checkpoint plus an input buffer, roughly halving state memory traffic and speeding up decoding kernels by 1.46x to 1.80x at batch size 256 on Blackwell Ultra B300 GPUs.
Apple researchers propose SELFCOMPACT, a scaffold that lets language models invoke a compaction tool guided by a lightweight rubric, matching or beating fixed-interval summarization at lower token cost on math and agentic search benchmarks.
Apple researchers describe Minions, a system that aggregates idle Apple Silicon GPUs across macOS devices to run large-scale machine learning inference when centralized GPU resources are constrained.
Apple researchers compared LLM and human annotators on MQM and Error Span Annotation across 70 language pairs and WMT23/WMT25 data, finding agreement varies by scheme, language and domain, with both sides facing distinct failure modes.
NVIDIA demonstrates a five-step workflow using Omniverse libraries and frontier AI models to convert an ABB YuMi robot from STEP files into a simulation-ready OpenUSD asset, covering appearance, physics, validation, and pick-and-place testing in Isaac Sim.
Apple researchers propose Normalizing Trajectory Models, which use conditional normalizing flows per reverse step to retain exact likelihood while generating high-quality images in four sampling steps, matching or beating strong baselines.
NVIDIA cuOpt introduces mPDLP, a multi-GPU solver that distributes large linear programming problems across NVLink-connected GPUs, cutting peak memory per GPU by up to 6x and speeding up solve times for problems impractical on a single GPU.
NVIDIA's Seattle Robotics Lab and Isaac team detail how a modular classical pipeline, not end-to-end learning, achieved over 95% success on GB300 tester tray busbar assembly, with a 160-second cycle time.
NVIDIA's DOCA GPUNetIO now serves as a shared GDA-KI foundation for NCCL, NVSHMEM, UCX/NIXL, and other libraries, with an open-source Verbs-focused implementation that can optionally call SDK functions via dlopen.
Apple researchers propose RISED, a method that uses rubric-based LLM judge profiles to select training data, supervise policy via self-distillation, and steer rollouts away from failure modes in multi-environment RL training.
NVIDIA's green contexts in CUDA 13.1 Runtime API allow explicit SM and workqueue partitioning within a process, cutting critical kernel latency from 0.140 ms to 0.007 ms on a 148-SM Blackwell GPU.
Together AI is working with IBM and NVIDIA to run a dedicated NVIDIA B300 GPU cluster on IBM Cloud with Spectrum-X Ethernet, as the first customer on that infrastructure. The company says it serves hundreds of trillions of tokens per month to over a million developers.
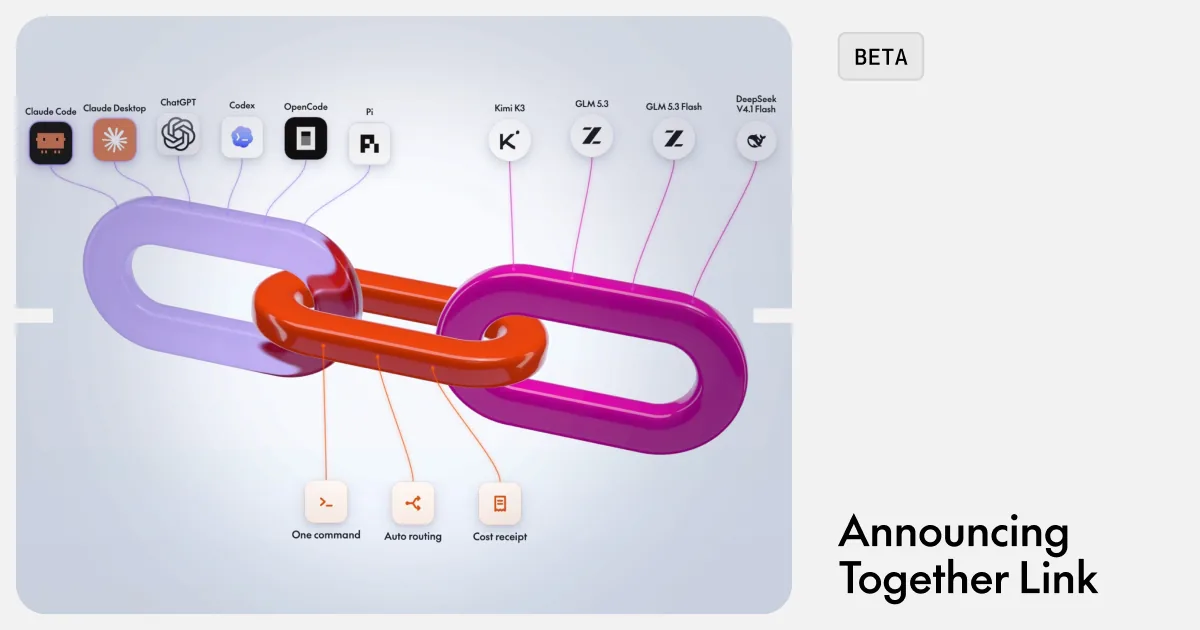
Together AI's new Link tool lets teams use Claude Code, Codex, and other agents with open models like GLM 5.3 and DeepSeek V4.1 Flash, with per-session cost tracking and a router that picks models based on task difficulty.
NVIDIA details a NeMo-based workflow to adapt Nemotron 3.5 ASR to Saudi Najdi and Hijazi dialects using minimal curation, replay mixing, and partial encoder unfreezing, cutting WER from 55.05% to 29.96% on target speech.
NVIDIA released DOCA AI agent skills on GitHub, providing agents with verified API signatures, hardware requirements, and build constraints. In a 65-prompt evaluation, agents with skills satisfied 100% of checklist items versus 19% without, reducing handwritten code by 73% in a demo.
NVIDIA's recsys-examples adds an end-to-end HSTU generative recommender workflow using PyTorch AOTI compilation and FlexKV-backed KV caching, reporting up to 5.93x lower latency on an RTX PRO 6000 Blackwell GPU.
NVIDIA has made cuObject client and server libraries generally available, adding an RDMA wire protocol for object storage. The xio-sig consortium expands to include cuObject, with Google Cloud and Microsoft involved, and a new SCADA Server SDK targets storage providers.
NVIDIA introduced a reference design that pairs OpenShell on Vera CPUs with Sentry on BlueField-4 DPUs, placing out-of-band policy enforcement on the node's only path to the model. The platform targets agents that drift from intended tasks and need independent, hardware-level controls.
Baseten details NVIDIA Nemotron 3 Diarization, an open end-to-end model that labels up to eight speakers at latencies from 0.32 to 30.4 seconds, with presets for batch, streaming, and real-time transcription. Benchmarks show up to 500 concurrent streams per RTX PRO 6000.
The v0.4.0 release of the ONNX Runtime WebGPU Plugin EP brings kernel optimizations, expanded operator support, and reliability fixes, including fused activations for Conv/MatMul, int8 KV cache quantization, and Linux AArch64 packages.
Dynamo v1.5.0, the 18th feature release, introduces pluggable router policies, session affinity modes, a standalone Sidecar for stock engines, and a new GPU Memory Service, among 658 merged pull requests.
PyTorch and Meta detail FlashAttention-4 with MXFP8 support, reaching 2.85 PF/s forward and 2 PF/s backward on LLM shapes, plus a zero-gather jagged module for Ads training.
NVIDIA reports a 10.4x throughput gain for dropless Mixture of Experts training in JAX on GB200, using grouped GEMM, fused dispatch and combine, and other optimizations. DeepSeek-V3 performance rose from 103 to 1,068 TFLOPS/GPU.
Fireworks AI benchmarks DeepSeek-V4.1-Flash, a 552B MoE with split input/output activations and KV cache cuts, matching GPT-6 Astra on DeepSWE at 1/15th the cost per task.
ONNX Runtime 1.30.0 expands CUDA generative AI with INT4 paged KV caches and speculative decoding, adds Go bindings, and gates CPU FP16 Gemm and MatMul on hardware acceleration with FP32 fallback.
vLLM v0.29.0 sets Model Runner V2 as the default for all models, adds support for Hy4-preview, Qwen3.8-Flash-Next, and Kimi K3 NVFP4, and introduces per-request speculative decoding acceptance stats in OpenAI API responses.
NVIDIA announced CUDA Rust, offering two tracks: cuda-oxide for SIMT kernels via a custom rustc backend, and cutile-rs for Tile-based programming on stable Rust. Both enforce memory safety at compile time, with cutile-rs already used in production inference engines.
SGLang v0.5.19 brings beam search, DeepEP v2 with ElasticBuffer, LayerNorm sequence parallelism, and support for new models like Qwen3.8 and Granite 4.2. Performance gains target Hopper, Blackwell, and AMD GPUs.
NVIDIA's walkthrough shows how Compute Sanitizer, the CCCL launch API, CUB primitives, pooled buffers, pinned memory, and per-thread streams cut an image pipeline from 6.8 seconds to 23 milliseconds.
NVIDIA and CrowdStrike built an adaptive agentic cybersecurity system using Nemotron 3 models, reporting a 2.5x detection improvement in backtesting and stronger generalization than a frontier system in live-fire tests.
Ollama's paid plans now use per-token rates with monthly usage credits, no service fees or session limits. Existing subscribers can stay on legacy pricing or upgrade in account settings.
Harvey's Tenet, post-trained from Kimi K3 with Fireworks, raises Legal Agent Benchmark all-pass from 10.8% to 19.7% and nearly doubles completed held-out tasks, with flat per-task cost.
vLLM v0.28.0 ships 584 commits with major Kimi-K3 performance work, end-to-end sparse MLA for DeepSeek V4, speculative decoding advances, and disk-based KV cache offloading. New defaults raise batched token limits and Blackwell CUDA graph capture.
Fireworks AI tested DeepSeek V4 Pro 0813 on CyberGym against Kimi K3, GPT-5.5, and Claude Opus 4.8. The open model recorded zero refusals across 840 tasks, beat GPT-5.5 on accuracy, and cost $2.50 per solved task versus $4.91 for Kimi K3.
SGLang v0.5.18 brings new diffusion and autoregressive models, overlapped checkpoint staging for faster startup, a TP LMHead all-to-all optimization, and NVFP4 checkpoint support on AMD GPUs.
Modular announced native support for Qualcomm's Cloud AI 100 Ultra NPU in its MAX and Mojo platform, letting developers run the same code on NVIDIA, AMD, and Qualcomm silicon without rewrites. The bring-up reached Gemma 4 serving in under six months.
llm-d v0.9.0 ships new batch gateway and latency predictor components, adds an Intel XPU SGLang image, and updates vLLM to v0.26.0 across CPU, ROCm, and TPU targets.
Dynamo v1.4.0, the 17th feature release, introduces experimental cross-datacenter prefix routing, a vLLM-compatible generate endpoint, and a 22.2% throughput gain in the Mocker. The update also brings NIXL RDMA transport for multi-node disaggregation and a rebuilt documentation site.
ONNX Runtime 1.29.0 brings PagedAttention with quantized KV cache, NVFP4 QMoE for CUDA, and WebGPU EP expansions, while deprecating WebGL and JSEP in onnxruntime-web. Security fixes cover path traversal and operator validation.
Modular has released Mojo 1.0, marking a stable foundation for the language after years of rapid evolution. The 26.5 release also adds new model families to MAX and simplifies installation.
The release lands Kimi K3 with a full stack, DeepSeek-V4 performance work, FlashAttention 4 FP8 KV cache on SM100, and Model Runner V2 expansion to non-generative workloads.
SGLang v0.5.17, released August 8, 2026, brings day-0 support for Kimi K3 and MiniMax-H3, a Rust frontend, and faster model loading. The release merges 582 pull requests from 194 contributors.
NVIDIA's Cosmos 3 world foundation model can be post-trained into robot policies that predict actions and future camera views. The 16B Nano and 4B Edge checkpoints serve on workstation or embedded hardware, with the Edge model running at 15 Hz on Jetson Thor.
NVIDIA shows how KAI Scheduler and vCluster let three teams share one L40S GPU with per-team quotas and isolated control planes, each seeing only their own workloads.
Together AI becomes the launch platform for Moonshot AI's open-weight models, starting with the 2.8-trillion-parameter Kimi K3. The partnership covers day-zero access, post-training options, and deployment across serverless, provisioned, and dedicated inference.
Fireworks AI shows how fine-tuning an LLM-based embedding model with contrastive learning and in-batch negatives improves domain retrieval by up to 39% nDCG@100, using only minutes of training time.
Qualcomm closed its acquisition of Modular on July 29, 2026. Mojo, MAX, and Modular Cloud continue as products, and Modular's CEO Chris Lattner becomes Qualcomm's EVP of Advanced AI Software and Platforms.
SGLang v0.5.16 introduces DSpark confidence-driven speculative decoding, adds support for the 975B-parameter Inkling model, and splits GLM-5.2 DSA cache layers under prefill CP to cut per-rank KV memory by about 74%.
PyTorch's Helion DSL now compiles to TPU via Pallas, with an autotuner choosing pipelining strategies. On flash attention, Helion hits 838 TFLOPs on TPU v7 and beats eager and compiled baselines across kernels.
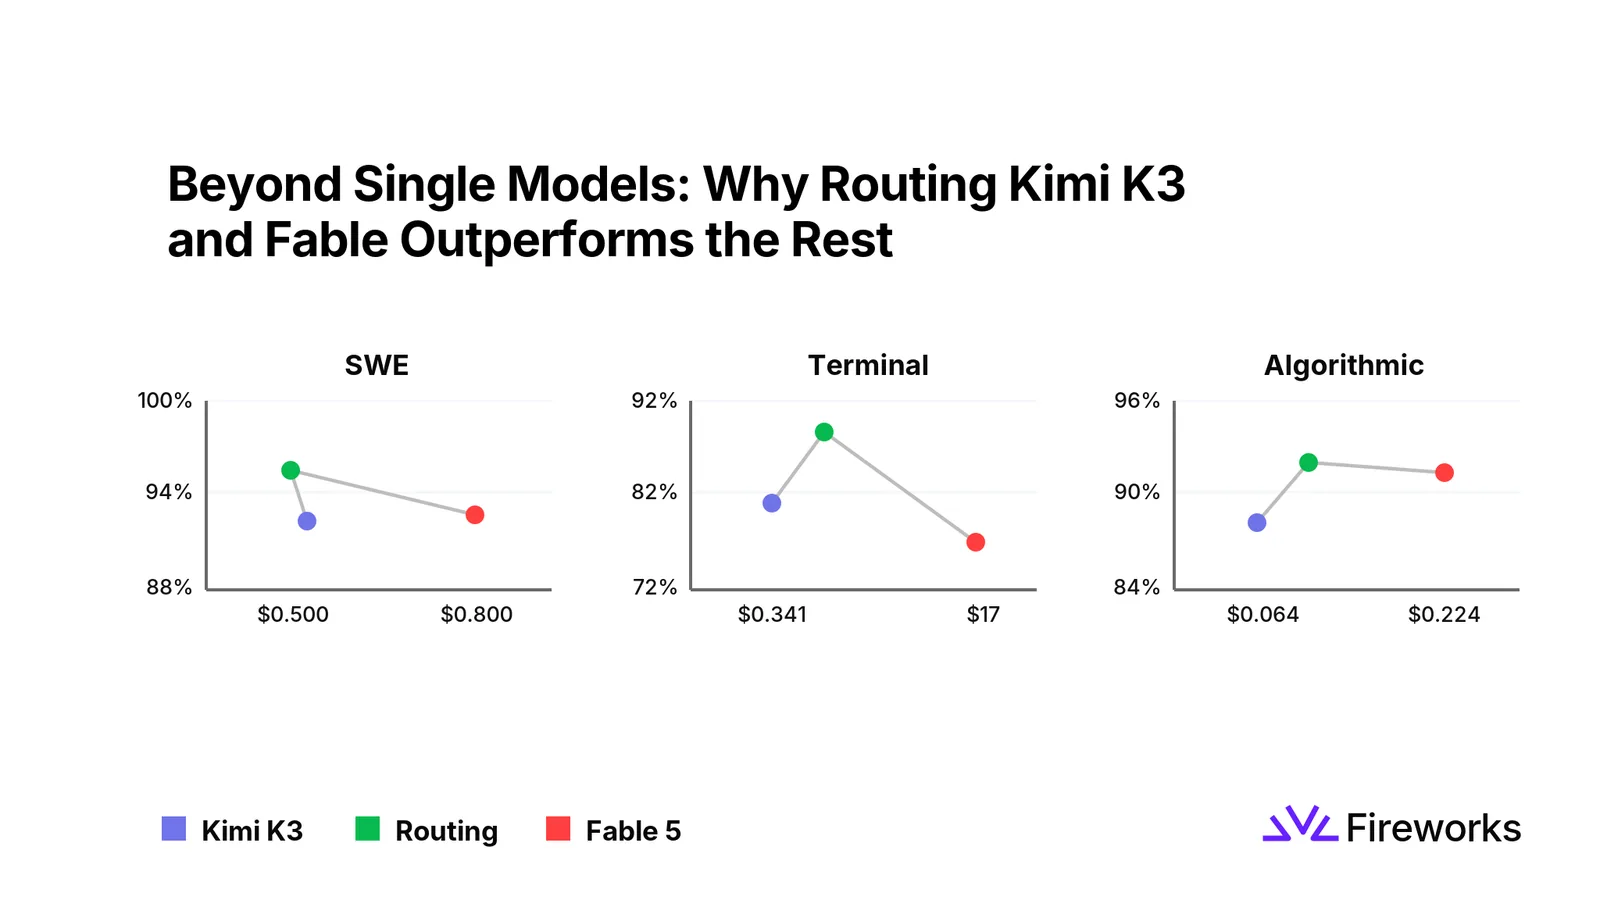
Fireworks AI ran about 1,030 agentic tasks through Kimi K3 and Fable 5, finding near-tied accuracy but up to 50x lower cost for K3 on long loops. Oracle routing hit 93% accuracy, suggesting a practical router could beat both single models.
Together AI explains the failure domains behind each reliability tier, from node failures to regional outages, and what architecture is required to survive them. The post also details how the company measures uptime and what to ask providers before committing.
Together AI shipped reliability and control features for GPU Clusters: passive health checks, auto node repair, a rebuilt Slurm-on-Kubernetes stack, external OIDC for Kubernetes RBAC, startup scripts, and an acceptance-test opt-out for smaller clusters.
vLLM v0.25.0 sets Model Runner V2 as the default for all dense models, deletes PagedAttention, and adds a streaming parser engine plus new speculative decoding drafters.
Ollama announced $88M in funding from Benchmark, Theory Ventures, 8VC, and others. The company says it serves 8.9 million developers and is used by 85% of the Fortune 500, with plans for hybrid inference and same-day model support.
MLX v0.32.0 brings CUDA JIT-compiled quantized matmul kernels with caching, Metal zero-copy DLPack sharing, Windows JIT compiler support, and a batch of correctness fixes across CPU, Metal, and CUDA backends.
The v0.24.0 release brings new model support, a streaming parser engine, DeepEP v2 integration, and a device selection change. It also expands Model Runner V2 to quantized models by default.
NVIDIA's Secure Agent Workspace Reference Design shifts agent execution from user devices to managed VMs, adding perimeter and runtime controls, credential proxies, and GitOps-based deployment for on-prem or cloud.
The release graduates multimodal serving, batch gateway, and flow control to production, adds non-Kubernetes routing for RL workloads, and shifts GPU and ROCm images to upstream vLLM builds.
llm-d v0.8.0 moves CUDA, ROCm, and XPU images to upstream vLLM builds, graduates multimodal, batch, and flow control to production, and adds multi-tier KV offloading with HMA support.
Groq announced $650 million in new growth capital to accelerate its AI inference cloud, scale to 200 MW by 2027, and expand its leadership team with hires from xAI, Meta, and Microsoft.
We count visits on the server, cookie-free. You can also let this browser tell us how long you read, how far you scroll and which links you follow. It stays with us.
 NVIDIAInferenceNews
 Apple
 Together AI



 llama.cpp
 Ollama