 NVIDIA
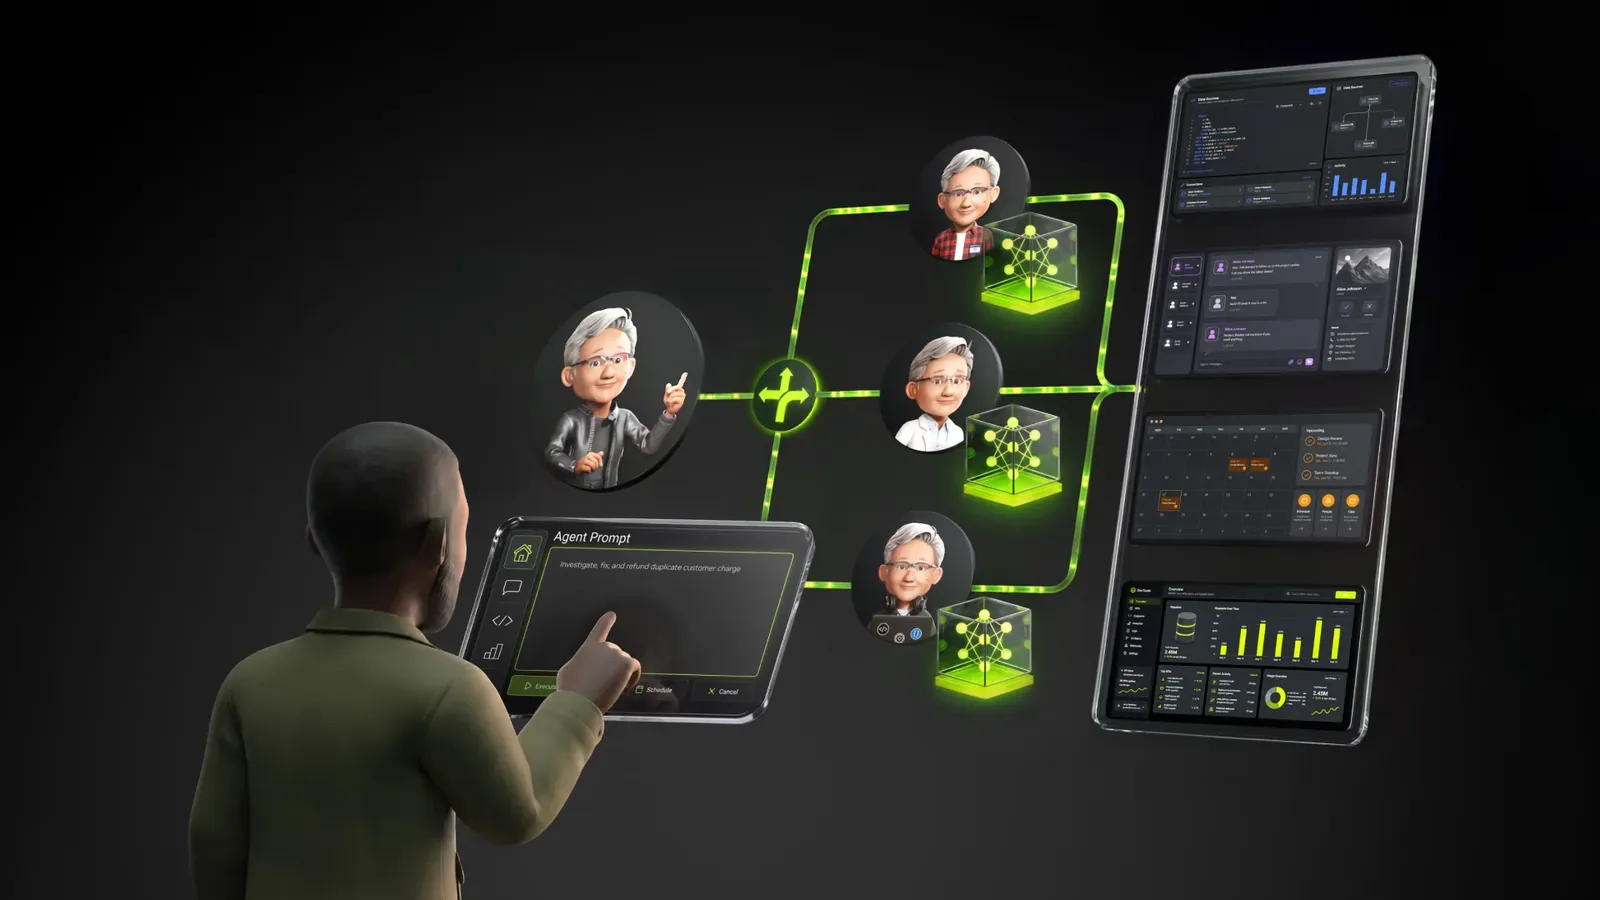
NVIDIA introduced Nemotron 3.5 Lightning, an open 30B mixture-of-experts (MoE) model with 3B active parameters, built for the execution layer of long-running AI agents. The model targets high-volume tasks like tool calls, result validation, and subagent delegation, where frontier reasoning models add cost and latency. It is designed for harnesses such as OpenClaw and Hermes Agent, supported by the NVIDIA NemoClaw open source security and management stack.
Design and customization
The MoE architecture routes each token to only a few of its many experts, so only a fraction of the parameters run per token. This gives the capacity of a larger dense model at the compute cost of a small one. Nemotron 3.5 Lightning is the smallest member of the Nemotron 3 family and includes speculative decoding with multi-token prediction baked in during pretraining, as with Nemotron 3 Super and Ultra. A dedicated MTP-boosting phase after training further improved MTP accuracy. Two draft models ship with the release: DSpark, recommended for DGX Spark inference and low concurrency data center workloads, and DFlash, which can be measured against the others. MTP is best suited for medium to high concurrency, with the optimal draft length decreasing as concurrency increases.
The model is customizable out of the box. Developers can fine-tune with LoRA or full SFT using NeMo Automodel and NeMo Megatron Bridge, and run reinforcement learning with NeMo RL and NeMo Gym. Weights, training data, and recipes are released under OpenMDW-1.1. The release also includes Nemotron-RL Agentic Terminal Pivot, an open agentic reinforcement learning dataset used to train some coding agent capabilities.
Routing and performance
NVIDIA also introduced NeMo Switchyard, a library that routes each request to the most capable and efficient model. Switchyard can expose Nemotron 3.5 Lightning as a routing target alongside open and closed models. Plans route up to frontier models, while execution routes down to Lightning, spending tokens efficiently.
On the Artificial Analysis Intelligence Index, which combines nine evaluations across agentic tasks, coding, scientific reasoning, and general intelligence, Nemotron 3.5 Lightning defines the accuracy-speed Pareto frontier for small open models. NVIDIA reports up to 4x output speed of similar-sized models. On PinchBench, the model reaches 86% accuracy while completing 10,000 tasks 30% faster than Qwen3.6 35B at similar accuracy.
Quantization and deployment
Nemotron 3.5 Lightning ships with an NVFP4 checkpoint alongside BF16, using the same specialized NVFP4 kernels that power Nemotron 3 Ultra across NVIDIA Blackwell, Hopper, and Ampere GPUs. The same file serves in data centers and on desktop DGX Spark systems. The model runs on local systems including NVIDIA Jetson, GeForce RTX 5090, and DGX Spark, and works with LM Studio, llama.cpp, Ollama, and Unsloth. NVIDIA worked with teams including EXO Labs to understand performance on DGX Spark, and the model sits on the Pareto frontier for small open models on the EXO Labs local.ai leaderboard.
A partner ecosystem supports the model across post-training, inference software, harnesses, cloud platforms, and hosted inference services. Developers can try the model on build.nvidia.com or through OpenRouter, download weights from Hugging Face and ModelScope, and use deployment guides for vLLM, SGLang, and TensorRT-LLM.
Sources & references
NVIDIA: NVIDIA Nemotron 3.5 Lightning Delivers Fast, Accurate Specialized Task Execution for Long-Running Agents ↗Source consulted: 2026-10-15


