 NVIDIA
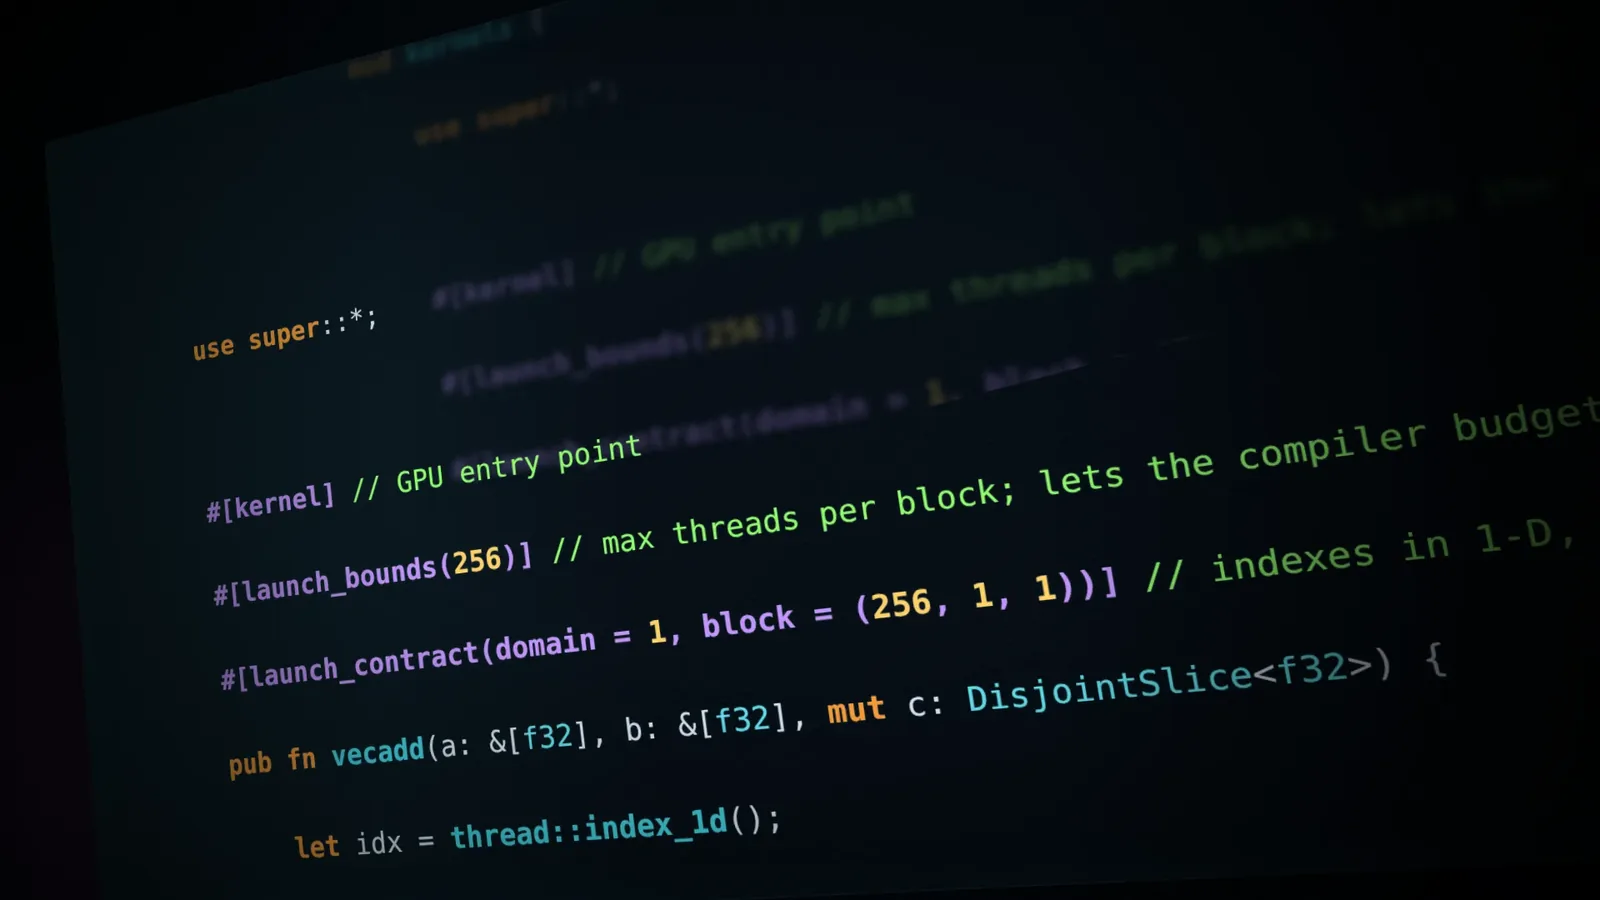
NVIDIA announced CUDA Rust in September 2026, a pair of projects that let developers write GPU kernels natively in Rust and compile them to PTX. The two tracks mirror the two programming models CUDA already supports: SIMT, where you describe what one thread does, and Tile, where the compiler handles thread mapping and memory layout.
The SIMT track is cuda-oxide, a custom rustc codegen backend. It routes kernel functions through Rust MIR, the Pliron IR framework, and LLVM IR down to PTX, while everything else goes through the standard backend. It requires Linux, a GPU with compute capability 8.0 or later, a CUDA toolkit 12.x or newer, clang with libclang headers, and a pinned nightly toolchain. The cargo oxide doctor command checks the setup, and cargo oxide run builds the backend on first use, which takes a while before later runs reuse the cache.
Safety by construction
Both tracks enforce memory safety at compile time, but they do it differently. In cuda-oxide, the kernel signature uses DisjointSlice for mutable output, a type that gives each thread exclusive access to its own element. Ordinary shared slices are readable by every thread. The launch is checked through a launch contract that declares the kernel's indexing and block size, and the prepare method validates the launch configuration against that contract and live device limits, returning a proof token that the safe launch method requires. Kernels without a contract only expose raw unsafe launch methods.
The Tile track, cutile-rs, works at a higher level. Each tile block runs the kernel body once as a single logical thread over one sub-tensor, and the compiler decides how many real GPU threads back it. The cutile module macro embeds the kernel's AST in the host binary and JIT-compiles it through CUDA Tile IR when first launched. Requirements are lighter: stable Rust 1.89 or newer, CUDA 13.3, and no custom LLVM or nightly toolchain. The project is published on crates.io, so there is nothing to clone.
In cutile-rs, partitioning on the host gives each tile block exclusive ownership of its own writable sub-tensor, using the same guarantee that Rust's mutable references already provide. Input shapes use a sentinel for dynamic dimensions, resolved at launch without recompiling.
Production readiness differs
cutile-rs is already in use: HuggingFace's Grout inference engine and mistral.rs both use it. cuda-oxide remains in early alpha. NVIDIA plans to support inter-language interoperability between CUDA Rust, CUDA C++, and CUDA Python, so the choice of frontend does not lock developers out of other ecosystems.
For inference engineers, the practical takeaway is that cutile-rs offers a path to write kernels in stable Rust today, with the compiler handling architecture-specific mapping. cuda-oxide provides finer control for SIMT-style kernels but requires a pinned nightly toolchain and a longer build process. Both projects are open source, with issues tracked on their repositories.
Sources & references
NVIDIA: Introducing CUDA Rust: Two Tracks for Writing GPU Kernels ↗Source consulted: 2026-10-15


