 NVIDIA
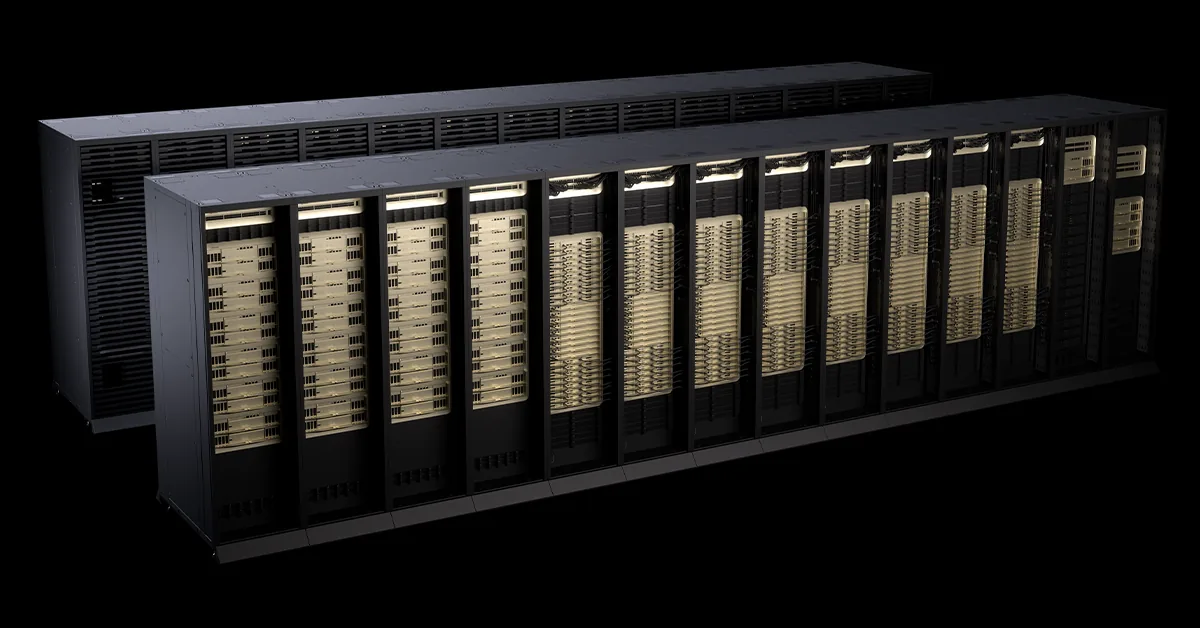
NVIDIA introduced the Vera Rubin platform as the next step for post-training workloads, framing the metric of intelligence per dollar as the key measure for agentic AI. The company argues that agentic models, which must plan, use tools, and recover from errors during a run, require continuous post-training rather than a one-time refinement step. That shift makes post-training the central workload of the agentic era, with compute demand growing because runs never stop, not because any single run is larger.
Post-training as a continuous loop
Post-training is where a model learns to write code, plan multistep tasks, and use search tools, according to NVIDIA. The process relies on reinforcement learning: the model writes an attempt in a forward pass, the attempt is scored, and the backward pass updates the weights. Running this loop at scale involves orchestrating thousands of environments generating rollouts in parallel, with rewards verified and updated weights flowing back into training. NVIDIA points to its NeMo libraries, including NeMo Gym for training environments and NeMo RL for distributed post-training, as tools that turn bespoke research code into repeatable infrastructure.
NVIDIA positions intelligence per dollar as a layer above cost per token. Cost per token measures the all-in cost of delivering 1 million tokens, while intelligence per dollar asks what it costs to build and maintain a model worth serving. The two metrics are nested: infrastructure that lowers cost per token also lowers the cost of building intelligence, and more capable models raise the value of every token served.
Nemotron 3 Ultra and platform claims
NVIDIA cites its open-weight Nemotron 3 Ultra, a 550-billion-parameter mixture-of-experts model, as an example of maximizing intelligence per dollar. The model scored 71.7% on SWE-bench verified, a coding benchmark where it produced working fixes for roughly seven in 10 real software bugs from open source projects. The post-training recipe runs on NeMo RL, with a fully disclosed setup.
For the Vera Rubin platform, NVIDIA claims it can train the largest models with one-fourth the GPUs of the Blackwell generation. The platform was codesigned to support more rollouts per run, more environments in play, and continuous post-training cycles. The company also says the Blackwell platform lowers cost per run, making frequent post-training economically viable.
Partner deployments
Prime Intellect continuously post-trains frontier open models on NVIDIA Blackwell and uses NVIDIA Dynamo for inference orchestration. With Vera Rubin, Prime Intellect plans to scale reinforcement learning environments and generate more rollouts per run. The company found that Vera delivers, on average, 30% greater throughput per CPU compared with alternative x86 architectures in realistic RL sandbox workloads.
Perplexity runs its RL post-training stack asynchronously across hundreds of NVIDIA GPUs, using an RDMA-based weight transfer engine that syncs trillion-parameter models in under two seconds between training and inference nodes. The resulting post-trained Qwen3 235B models are served on NVIDIA GB200 NVL72 systems.
Together AI offers post-training as a service, including supervised fine-tuning, RL, and direct preference optimization, delivered through an API and SDK on its AI Native Cloud platform. The service runs on NVIDIA's platform and optimized kernel libraries, and Together AI is looking to harness the Vera Rubin platform next.
Sources & references
NVIDIA: NVIDIA Vera Rubin Maximizes Intelligence per Dollar for Post-Training Workloads — a Key Metric for Agentic AI ↗Source consulted: 2026-10-15


