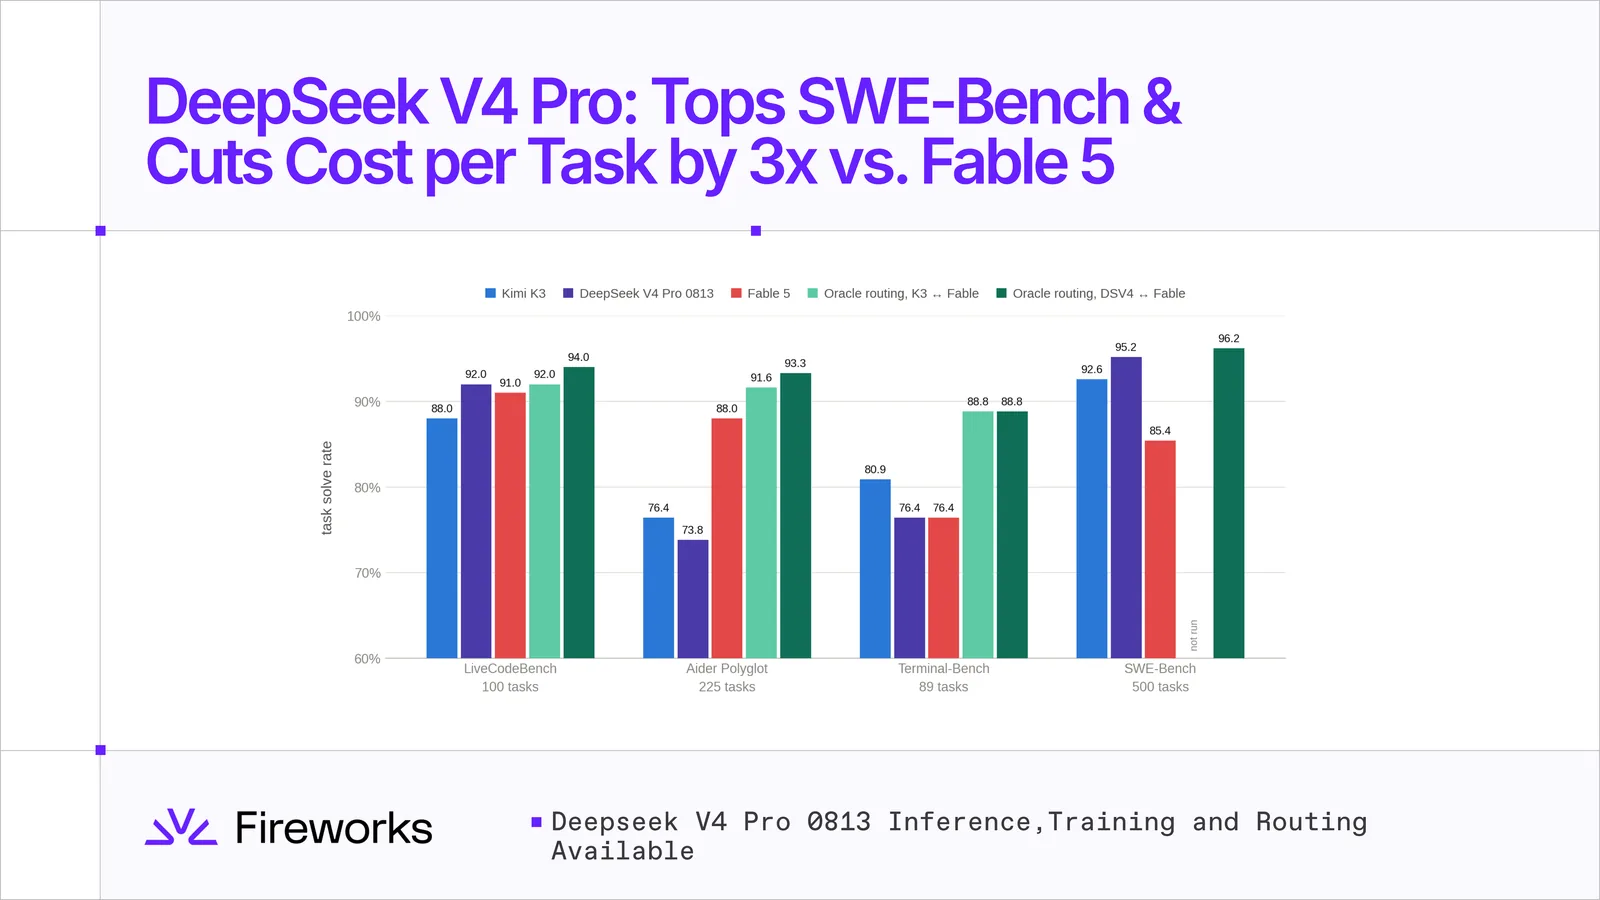
Fireworks AI published benchmark results for DeepSeek V4 Pro 0813, comparing it against Kimi K3 and Fable 5 across four code-focused evaluation families. The model tops SWE-Bench Verified with 95.2% and LiveCodeBench v6 with 92.0%, while Fable 5 leads Aider Polyglot with 88.0%. On Terminal-Bench 2.1, DeepSeek V4 Pro and Fable 5 tie at 76.4%, but the cost picture differs sharply.
Cost per solved task
Fireworks reports DeepSeek V4 Pro costs $0.309 per solved task on SWE-Bench, versus $0.808 for Fable 5, and $0.040 on LiveCodeBench, versus $0.225. On Terminal-Bench, Fable 5 scores the same but requires multiple attempts, bringing task costs to $16.85. Scored on its first attempt, Fable 5 hits 74.2%, but cost per task jumps to $75.40. Fireworks notes that internal evaluations rely on this primary-run baseline.
DeepSeek V4 Pro is weaker on multi-language breadth. On Aider Polyglot, it stays strong in Rust at 90.0% and C++ at 80.8%, but falls to 48.9% on Java, the largest slice at 47 tasks, compared to Fable 5's 74.5%. Fireworks attributes nearly the entire gap to Java performance and suggests that Java-heavy codebases may hit bottlenecks with a single model.
Routing changes the bill
Fireworks tested oracle routing between DeepSeek V4 Pro and Fable 5, picking the better model per task and breaking ties toward lower cost. On a 409-task combined cohort, routing hits 92.4% against Fable 5 alone at 86.6%, at $0.279 per task versus Fable's $4.510, a sixteen-fold cost reduction. Notably, 86.3% of tasks route to V4 Pro, meaning the expensive model becomes the exception rather than the default.
Every V4 Pro pairing beats the equivalent K3 pairing. LiveCodeBench hits 94.0% against 92.0%, Aider reaches 93.3% against 91.6%, and the combined cohort lands at 92.5% against 91.1%. Fireworks notes that V4 Pro is a better routing partner than K3 even though K3 scores higher on CyberGym, because V4 Pro's wins land on tasks Fable 5 misses. The company cautions that oracle routing is an upper bound computed after the fact, not a deployable policy, and that real routers capture only a fraction of it.
Training and harness notes
DeepSeek V4 Pro training is live on Fireworks with support for SFT, DPO, and RFT. Fireworks says training and serving run on the same co-optimized backend, so production performance matches training benchmarks. The company also flags that DeepSeek's own published runs use the DeepSeek Harness, a native agent runtime that speaks DeepSeek V4's tool semantics instead of a generic OpenAI-style interface. DeepSeek has not shipped a standard chat template for this model, so small serialization mismatches can silently drop performance. Fireworks found that a minimal-first setup, starting with a bare bash and editor surface before promoting to the standard catalog, brings the model closer to DeepSeek's own benchmark setup.
Fireworks also reports zero refusals and zero output-length truncations across 840 traced adversarial security runs, which it says ensures agents complete workloads without hitting unexpected guardrails. The model provides a 1M-token context window with native tool calling and preserved reasoning history, targeting long-horizon agentic workloads.
Sources & references
Fireworks AI: DeepSeek V4 Pro: Tops SWE-Bench & Cuts Cost per Task by 3x vs. Fable 5 ↗Source consulted: 2026-10-15

 NVIDIA

