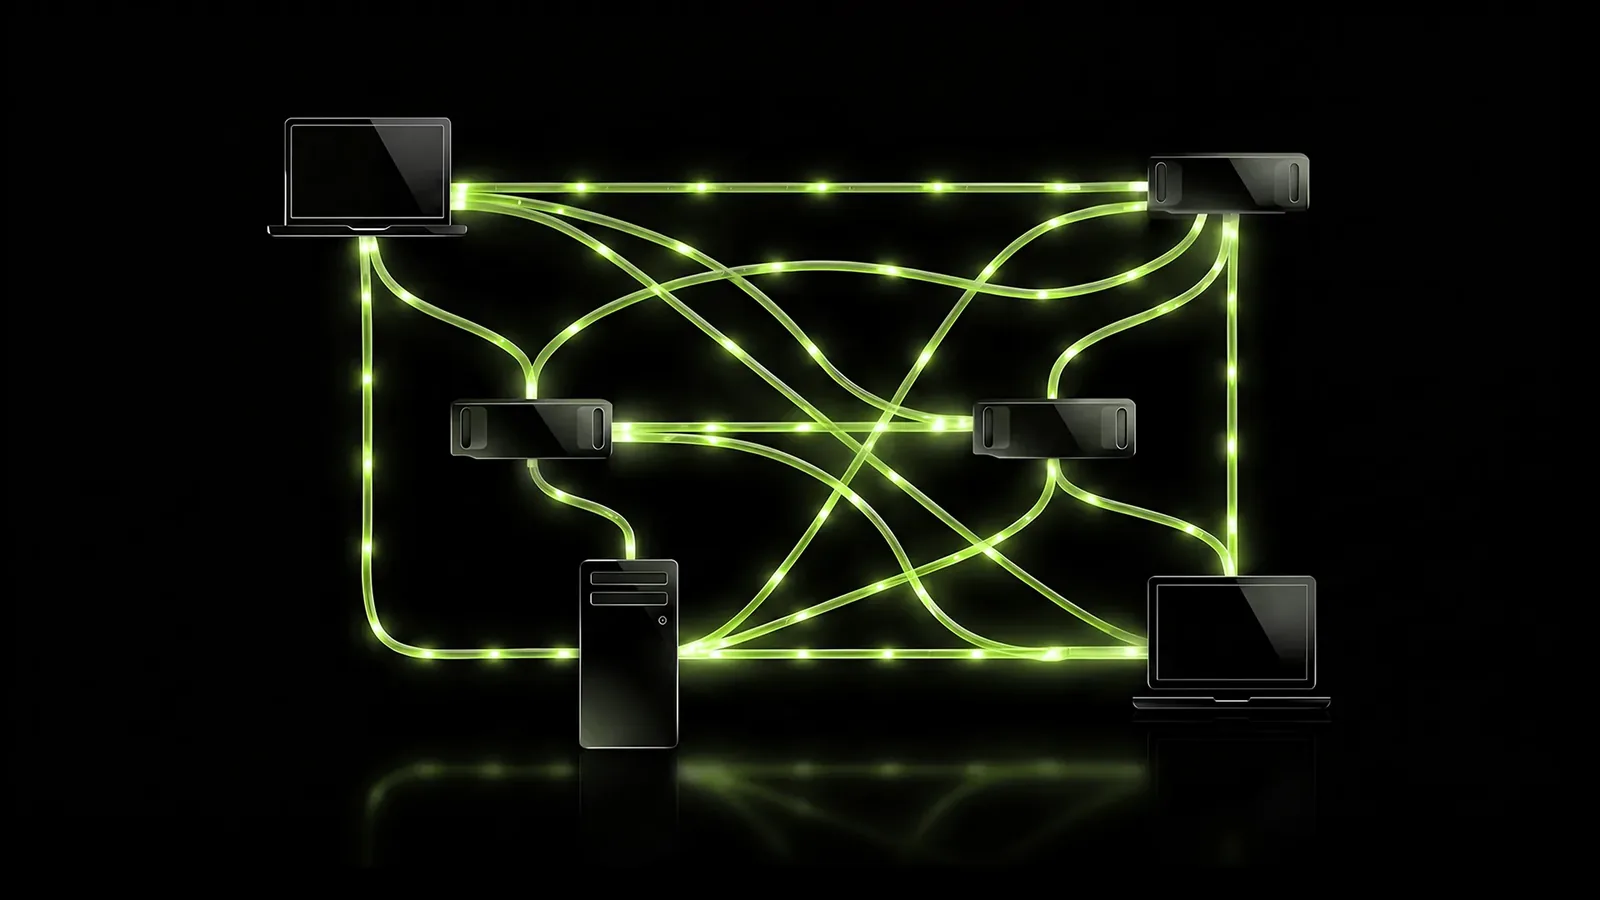
NVIDIA's PAIR beta proxies Ollama and LM Studio to schedule independent inference requests across paired local systems, cutting a five-subagent demo from 18 minutes to 8 minutes 48 seconds on a three-device cluster.
Ollama Cloud integrates with Fly.io Sprites, letting AI agents in sandboxed Linux VMs call models like kimi-k3 and glm-5.3 without exposing API keys. A gateway adds keys per Sprite, and access is blocked by default.
Ollama's release candidate v0.40.4-rc1 introduces Kev decision scoring to the MLX backend, loading Kev models with FP32 decision heads and release metadata, plus System One scoring with shared-state caching.
Ollama's paid plans now use per-token rates with monthly usage credits, no service fees or session limits. Existing subscribers can stay on legacy pricing or upgrade in account settings.
Ollama announced $88M in funding from Benchmark, Theory Ventures, 8VC, and others. The company says it serves 8.9 million developers and is used by 85% of the Fortune 500, with plans for hybrid inference and same-day model support.
We count visits on the server, cookie-free. You can also let this browser tell us how long you read, how far you scroll and which links you follow. It stays with us.
 NVIDIAInferenceNews
 Ollama