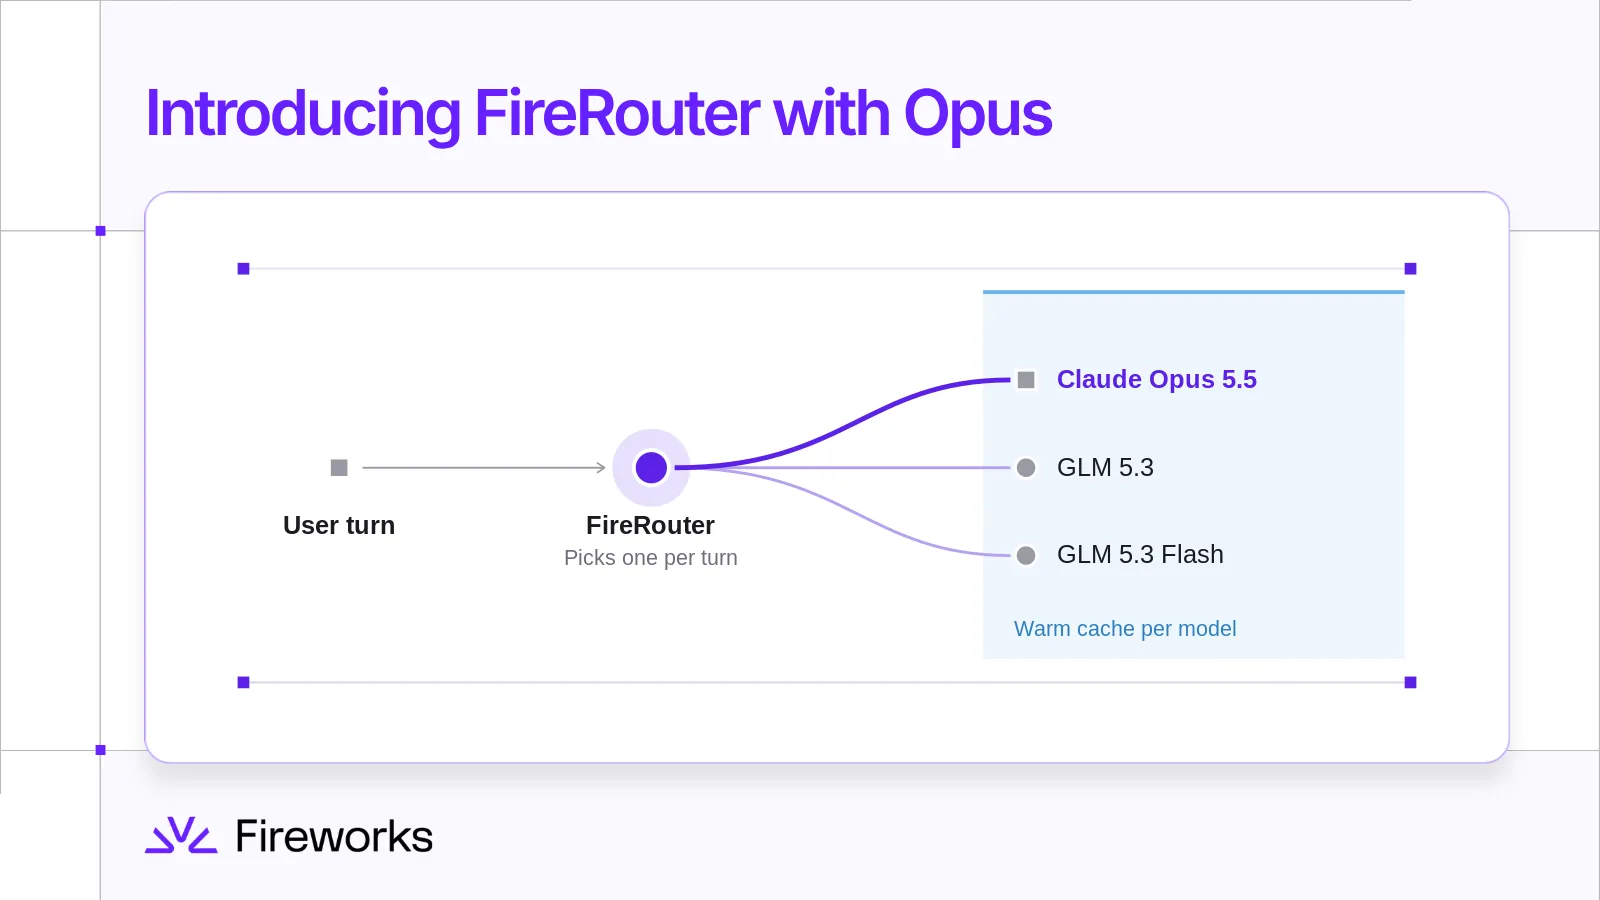
Fireworks AI's FireRouter with Opus routes coding turns among Opus 5.5, GLM 5.3, and GLM 5.3 Flash, cutting costs 57% in internal tests while retaining 98.1% of Opus-only accuracy. It is available as a CLI tool or serverless endpoint.
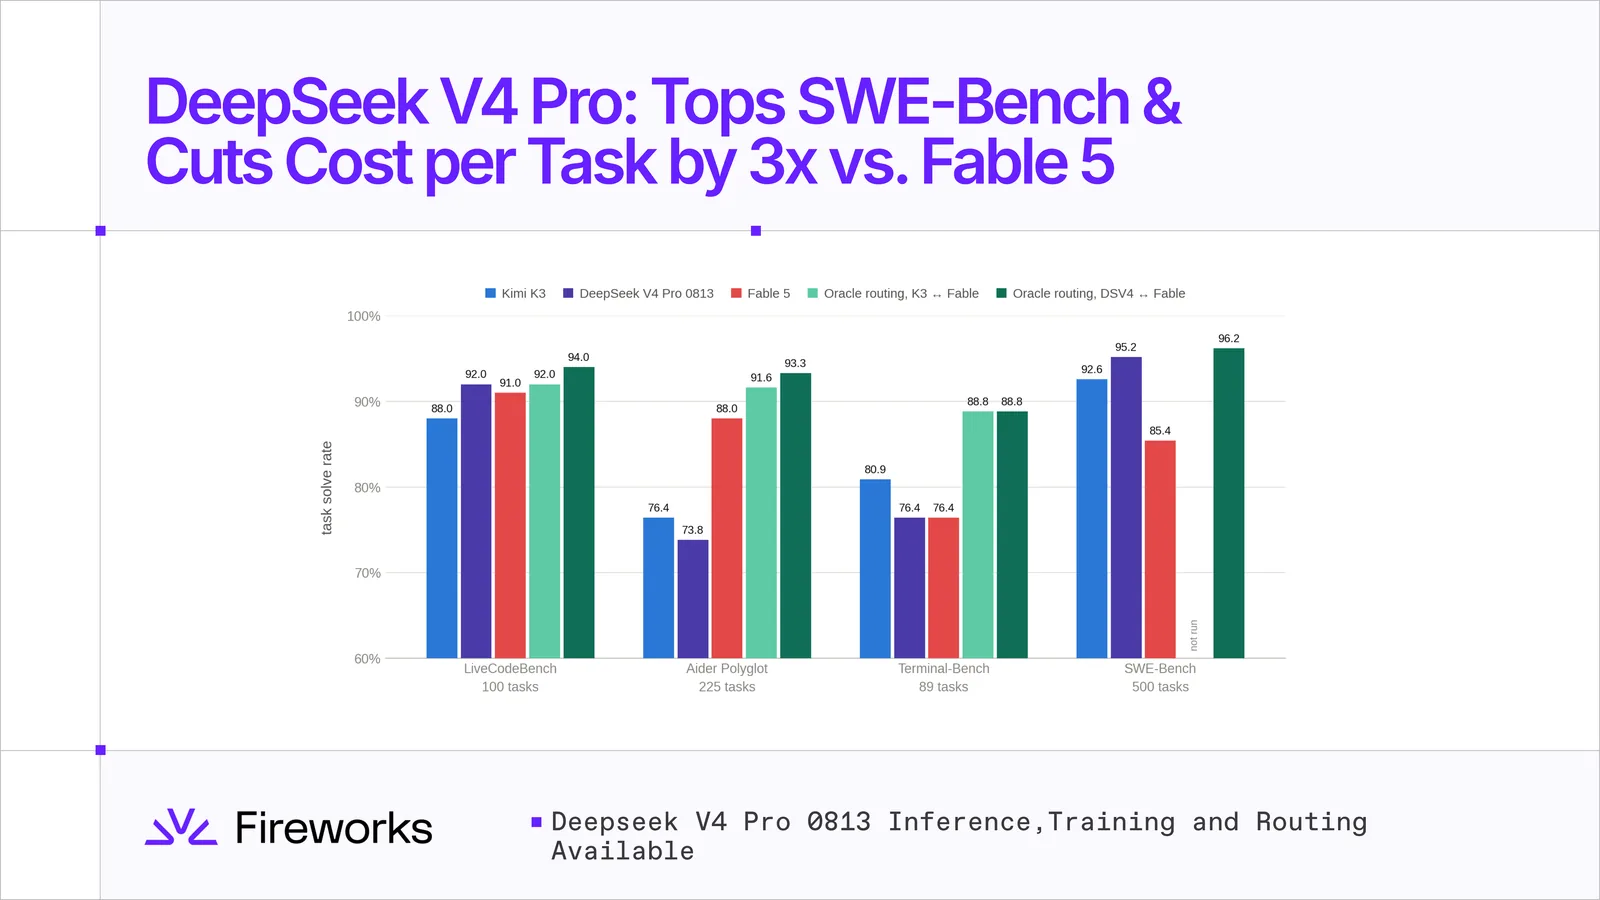
Fireworks AI reports DeepSeek V4 Pro 0813 leads its SWE-Bench and LiveCodeBench runs, cuts cost per solved task versus Fable 5, and pairs better with routing. Training is live.
Fireworks AI fitted Jacobian Lens probes on Kimi K3 and Qwen3.5-9B, finding task-related vocabulary in hidden states before it appears in output. The method transferred across architectures, with 19 of 20 word lists matching on Qwen.
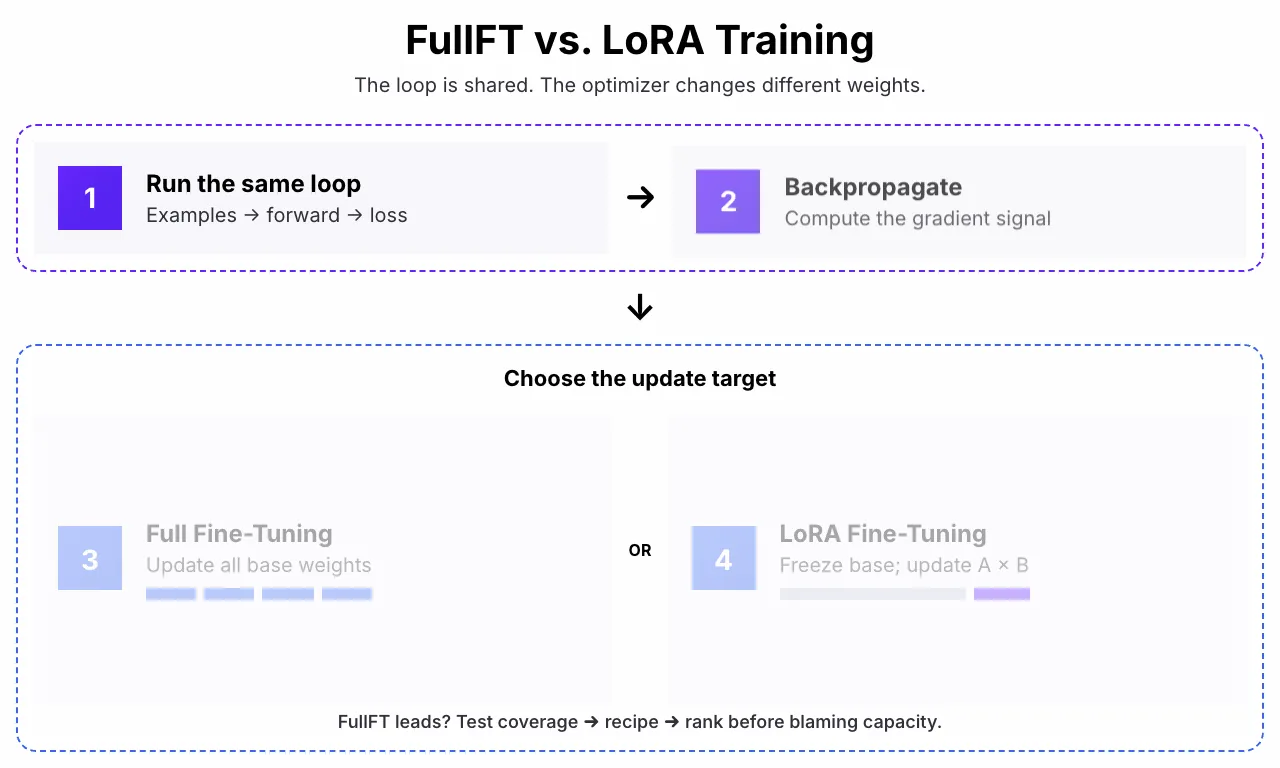
Fireworks AI ran controlled experiments on Qwen3.5-9B to isolate whether data coverage, optimization, or adapter rank explains LoRA's gap to FullFT. The results show that tuning the learning rate or broadening data often closes the gap, while rank matters only in some tasks.
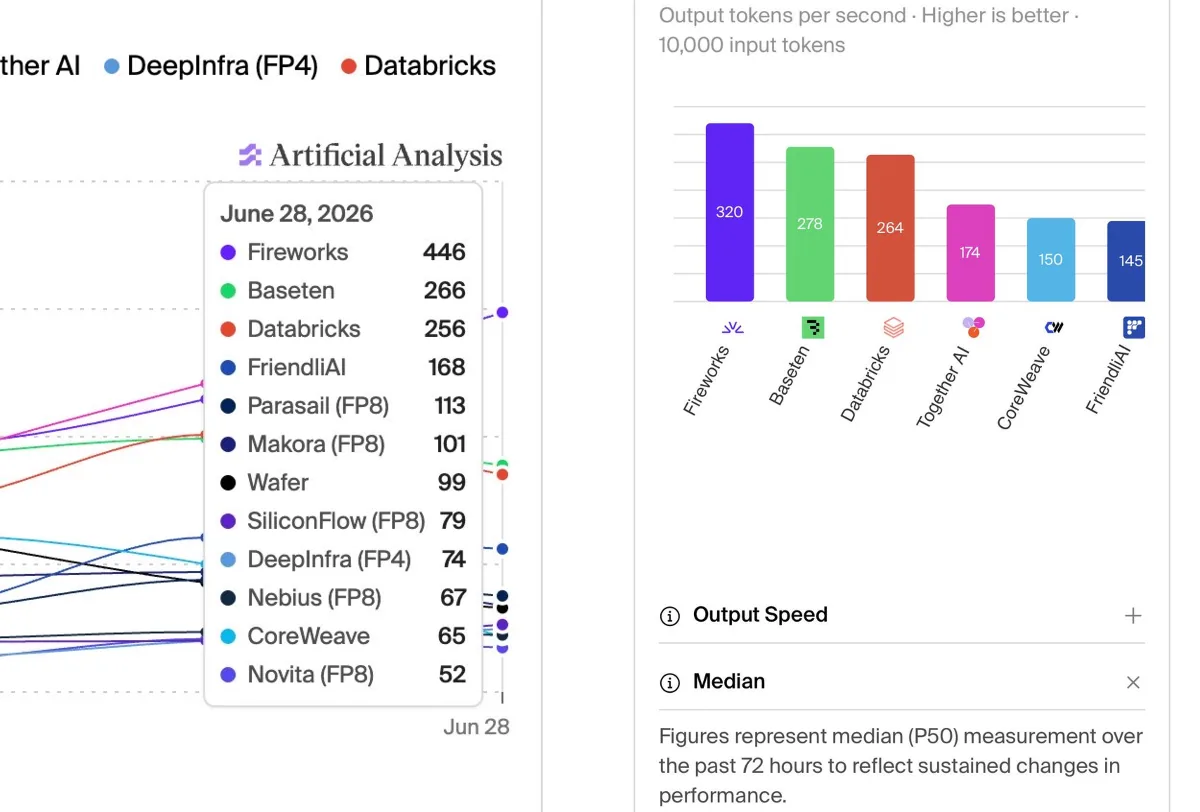
Fireworks AI released GLM 5.2 Fast, a serverless serving path that runs about 2x faster than its Standard route on the same model, with no reserved GPUs. The company details how it splits expert and attention sharding, uses sparse attention, and keeps cached input tokens at $0.14 per 1M.
Fireworks AI details how Cursor's Composer 2, built on Kimi 2.5, uses distributed reinforcement learning across global clusters, with compressed weight updates and reused inference to cut costs and improve coding performance.
Fireworks AI now provides managed training infrastructure for GLM 5.2 that keeps training and serving numerically identical, with zero KLD end to end. The service targets reinforcement learning on frontier models, addressing batch invariance and deterministic numerics.
Fireworks AI reports that pairing open-source worker models with a single closed-source review call from Claude Opus 4.8 improves success rates across three benchmarks while cutting inference costs by 19% to 67%.
Fireworks AI benchmarks DeepSeek-V4.1-Flash, a 552B MoE with split input/output activations and KV cache cuts, matching GPT-6 Astra on DeepSWE at 1/15th the cost per task.
Fireworks AI tested DeepSeek V4 Pro 0813 on CyberGym against Kimi K3, GPT-5.5, and Claude Opus 4.8. The open model recorded zero refusals across 840 tasks, beat GPT-5.5 on accuracy, and cost $2.50 per solved task versus $4.91 for Kimi K3.
Fireworks AI shows how fine-tuning an LLM-based embedding model with contrastive learning and in-batch negatives improves domain retrieval by up to 39% nDCG@100, using only minutes of training time.
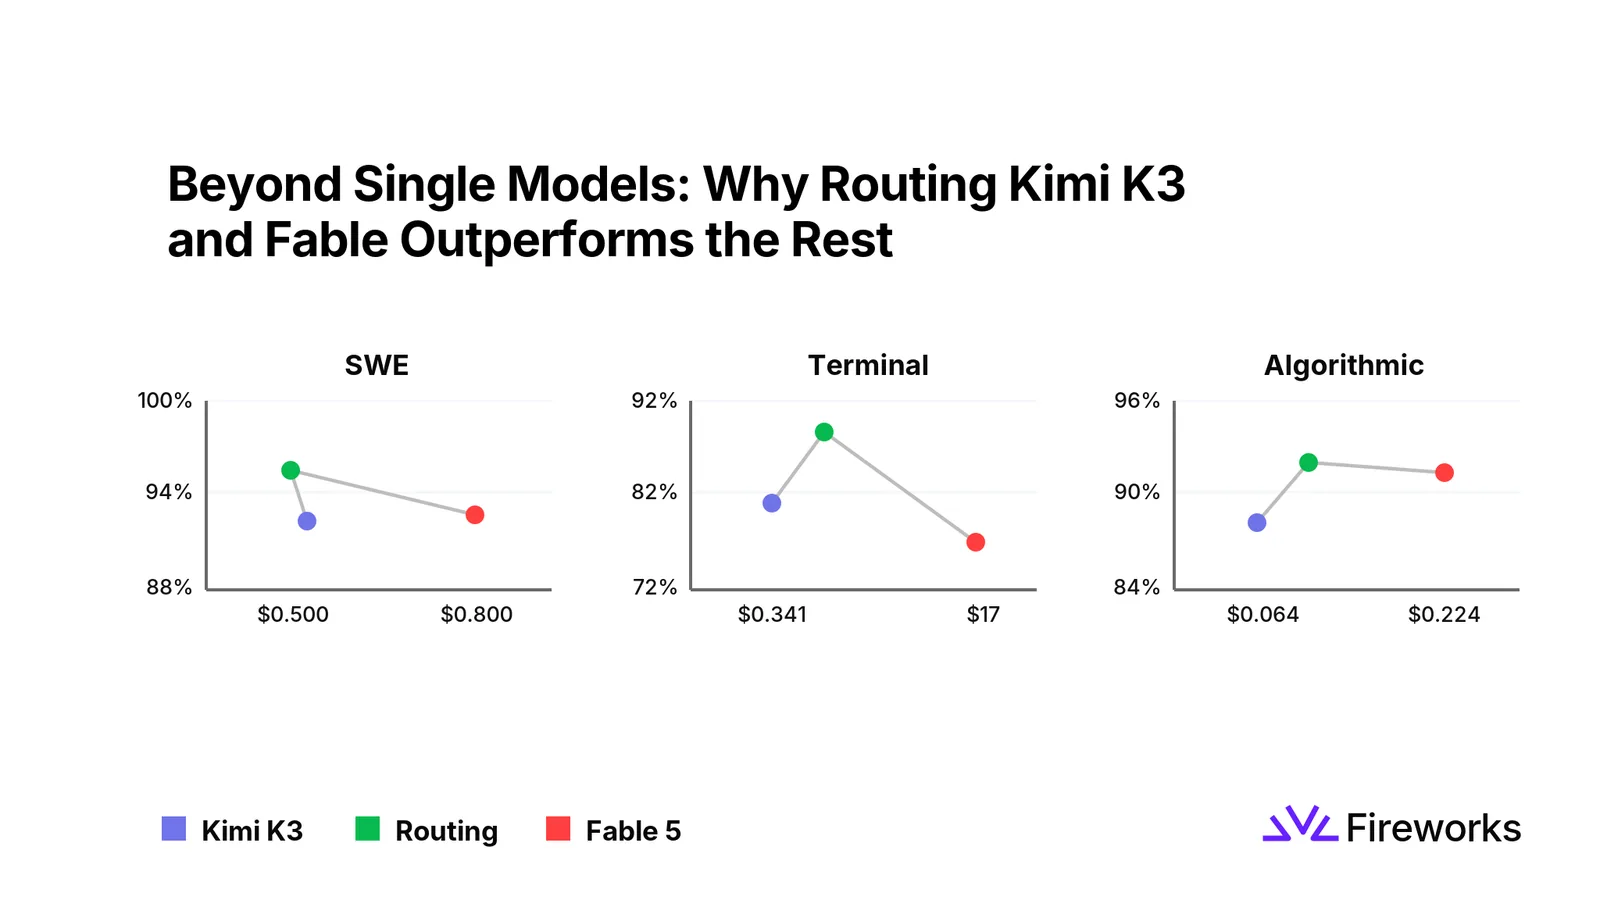
Fireworks AI ran about 1,030 agentic tasks through Kimi K3 and Fable 5, finding near-tied accuracy but up to 50x lower cost for K3 on long loops. Oracle routing hit 93% accuracy, suggesting a practical router could beat both single models.
We count visits on the server, cookie-free. You can also let this browser tell us how long you read, how far you scroll and which links you follow. It stays with us.